Article
Entropy Data with Databricks
André Deuerling
Product Engineer, Entropy Data ·
Databricks is a great platform to store, process, and analyze your data products. Entropy Data integrates well with Databricks. Entropy Data adds a user-friendly data marketplace for users and agents, data product and data contract management capabilities, a semantic editor experience with full downstream integrations, and governance features to make a data product architecture a success.
Why Databricks is not enough
Databricks is a great platform for data engineers to write notebooks, build data pipelines, deploy DABs, and train models. Genie provides great value for writing queries and analyzing the data.
Entropy Data extends Databricks with capabilities that go beyond data engineering:
- Data marketplace
- Data product ownership, management, and governance
- Data contract enforcement
- Semantic data with open standards
- Multi-platform metadata distribution
Entropy Data integrates well with Databricks to read information from Databricks and write semantic data back. But Entropy Data also populates other application, data, and AI platforms with the same semantic definitions.
Data marketplace for users and agents
Data is becoming the driver for decision-making, new business processes, and most agent use cases. A challenge is to find trustworthy data. Entropy Data optimizes for an easy-to-use data marketplace that helps data users and agents find the semantically relevant data products, with trust signals to evaluate them.
In contrast to technical data catalogs, Entropy Data focuses on the few hundred high-quality data products, not the millions of technical data assets.
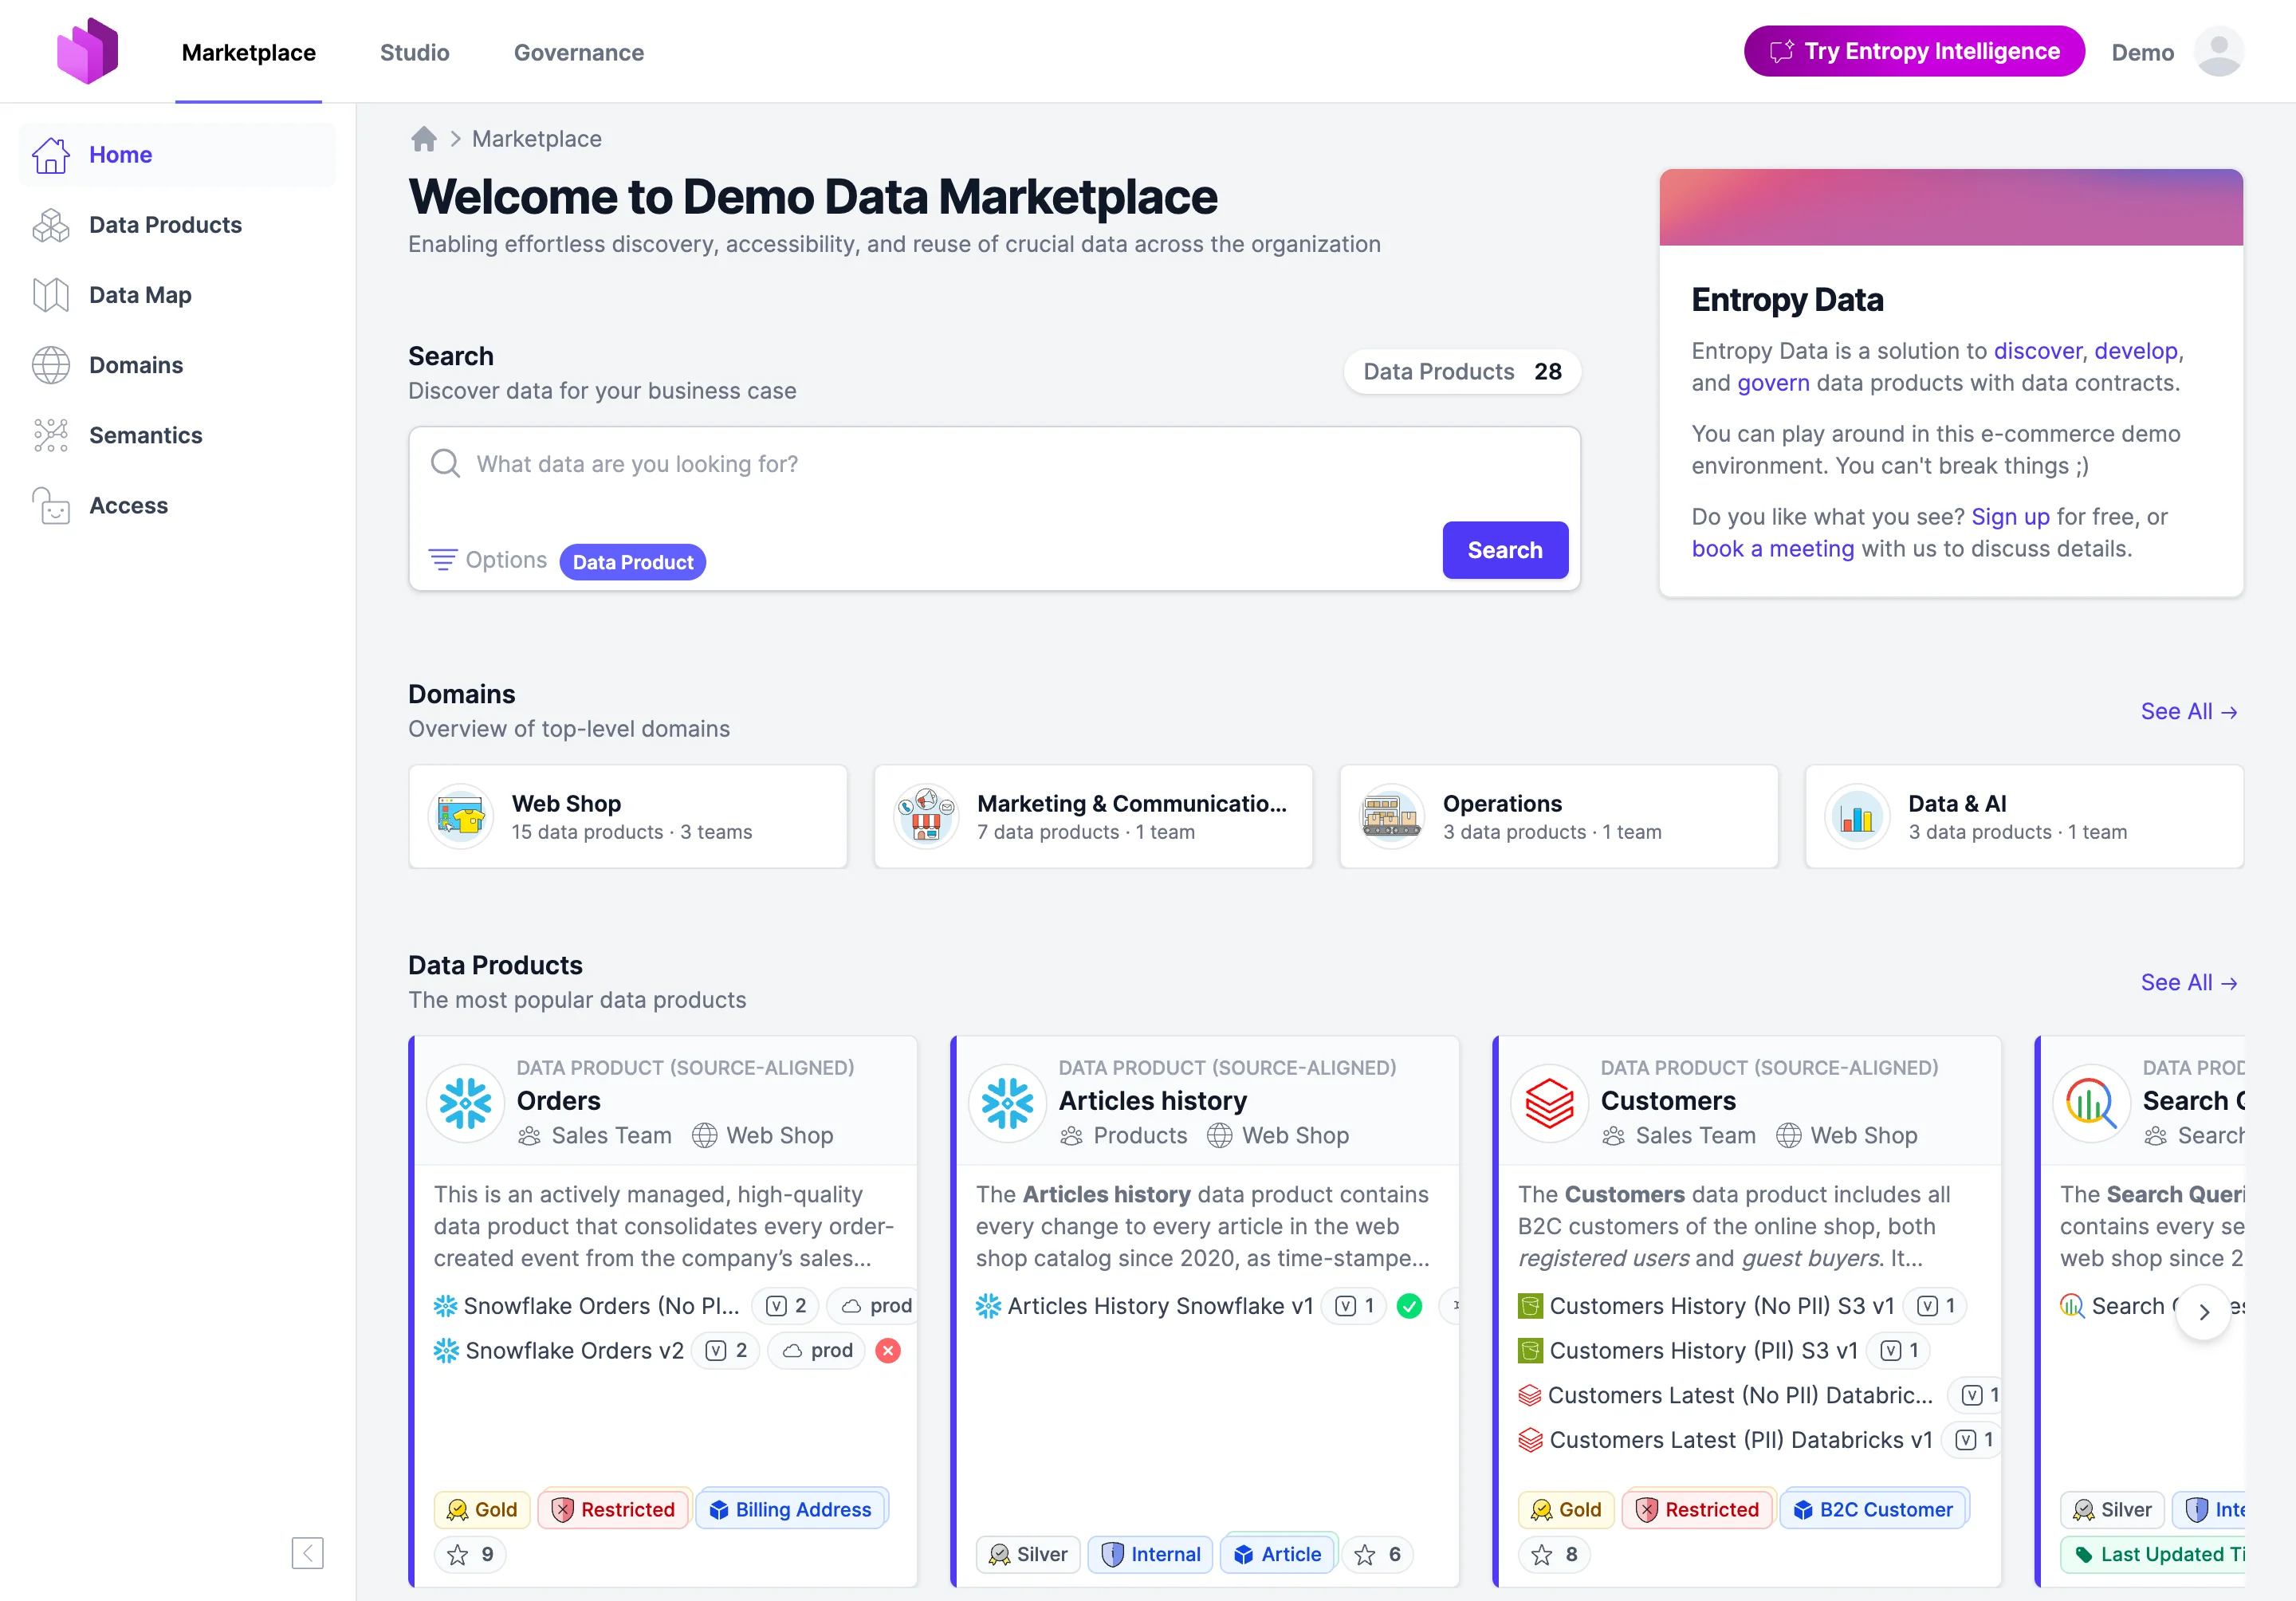
A colleague from marketing who needs customer data for a campaign does not open a catalog of tables. They open one page, type what they are looking for in their own words, and get data products back, because the search works on the descriptions, the contracts, and the semantic business definitions. They can also browse: they start from the domains, filter the products by team, type, certification, classification, or tag, and switch between cards and a list until the candidates are down to two or three.
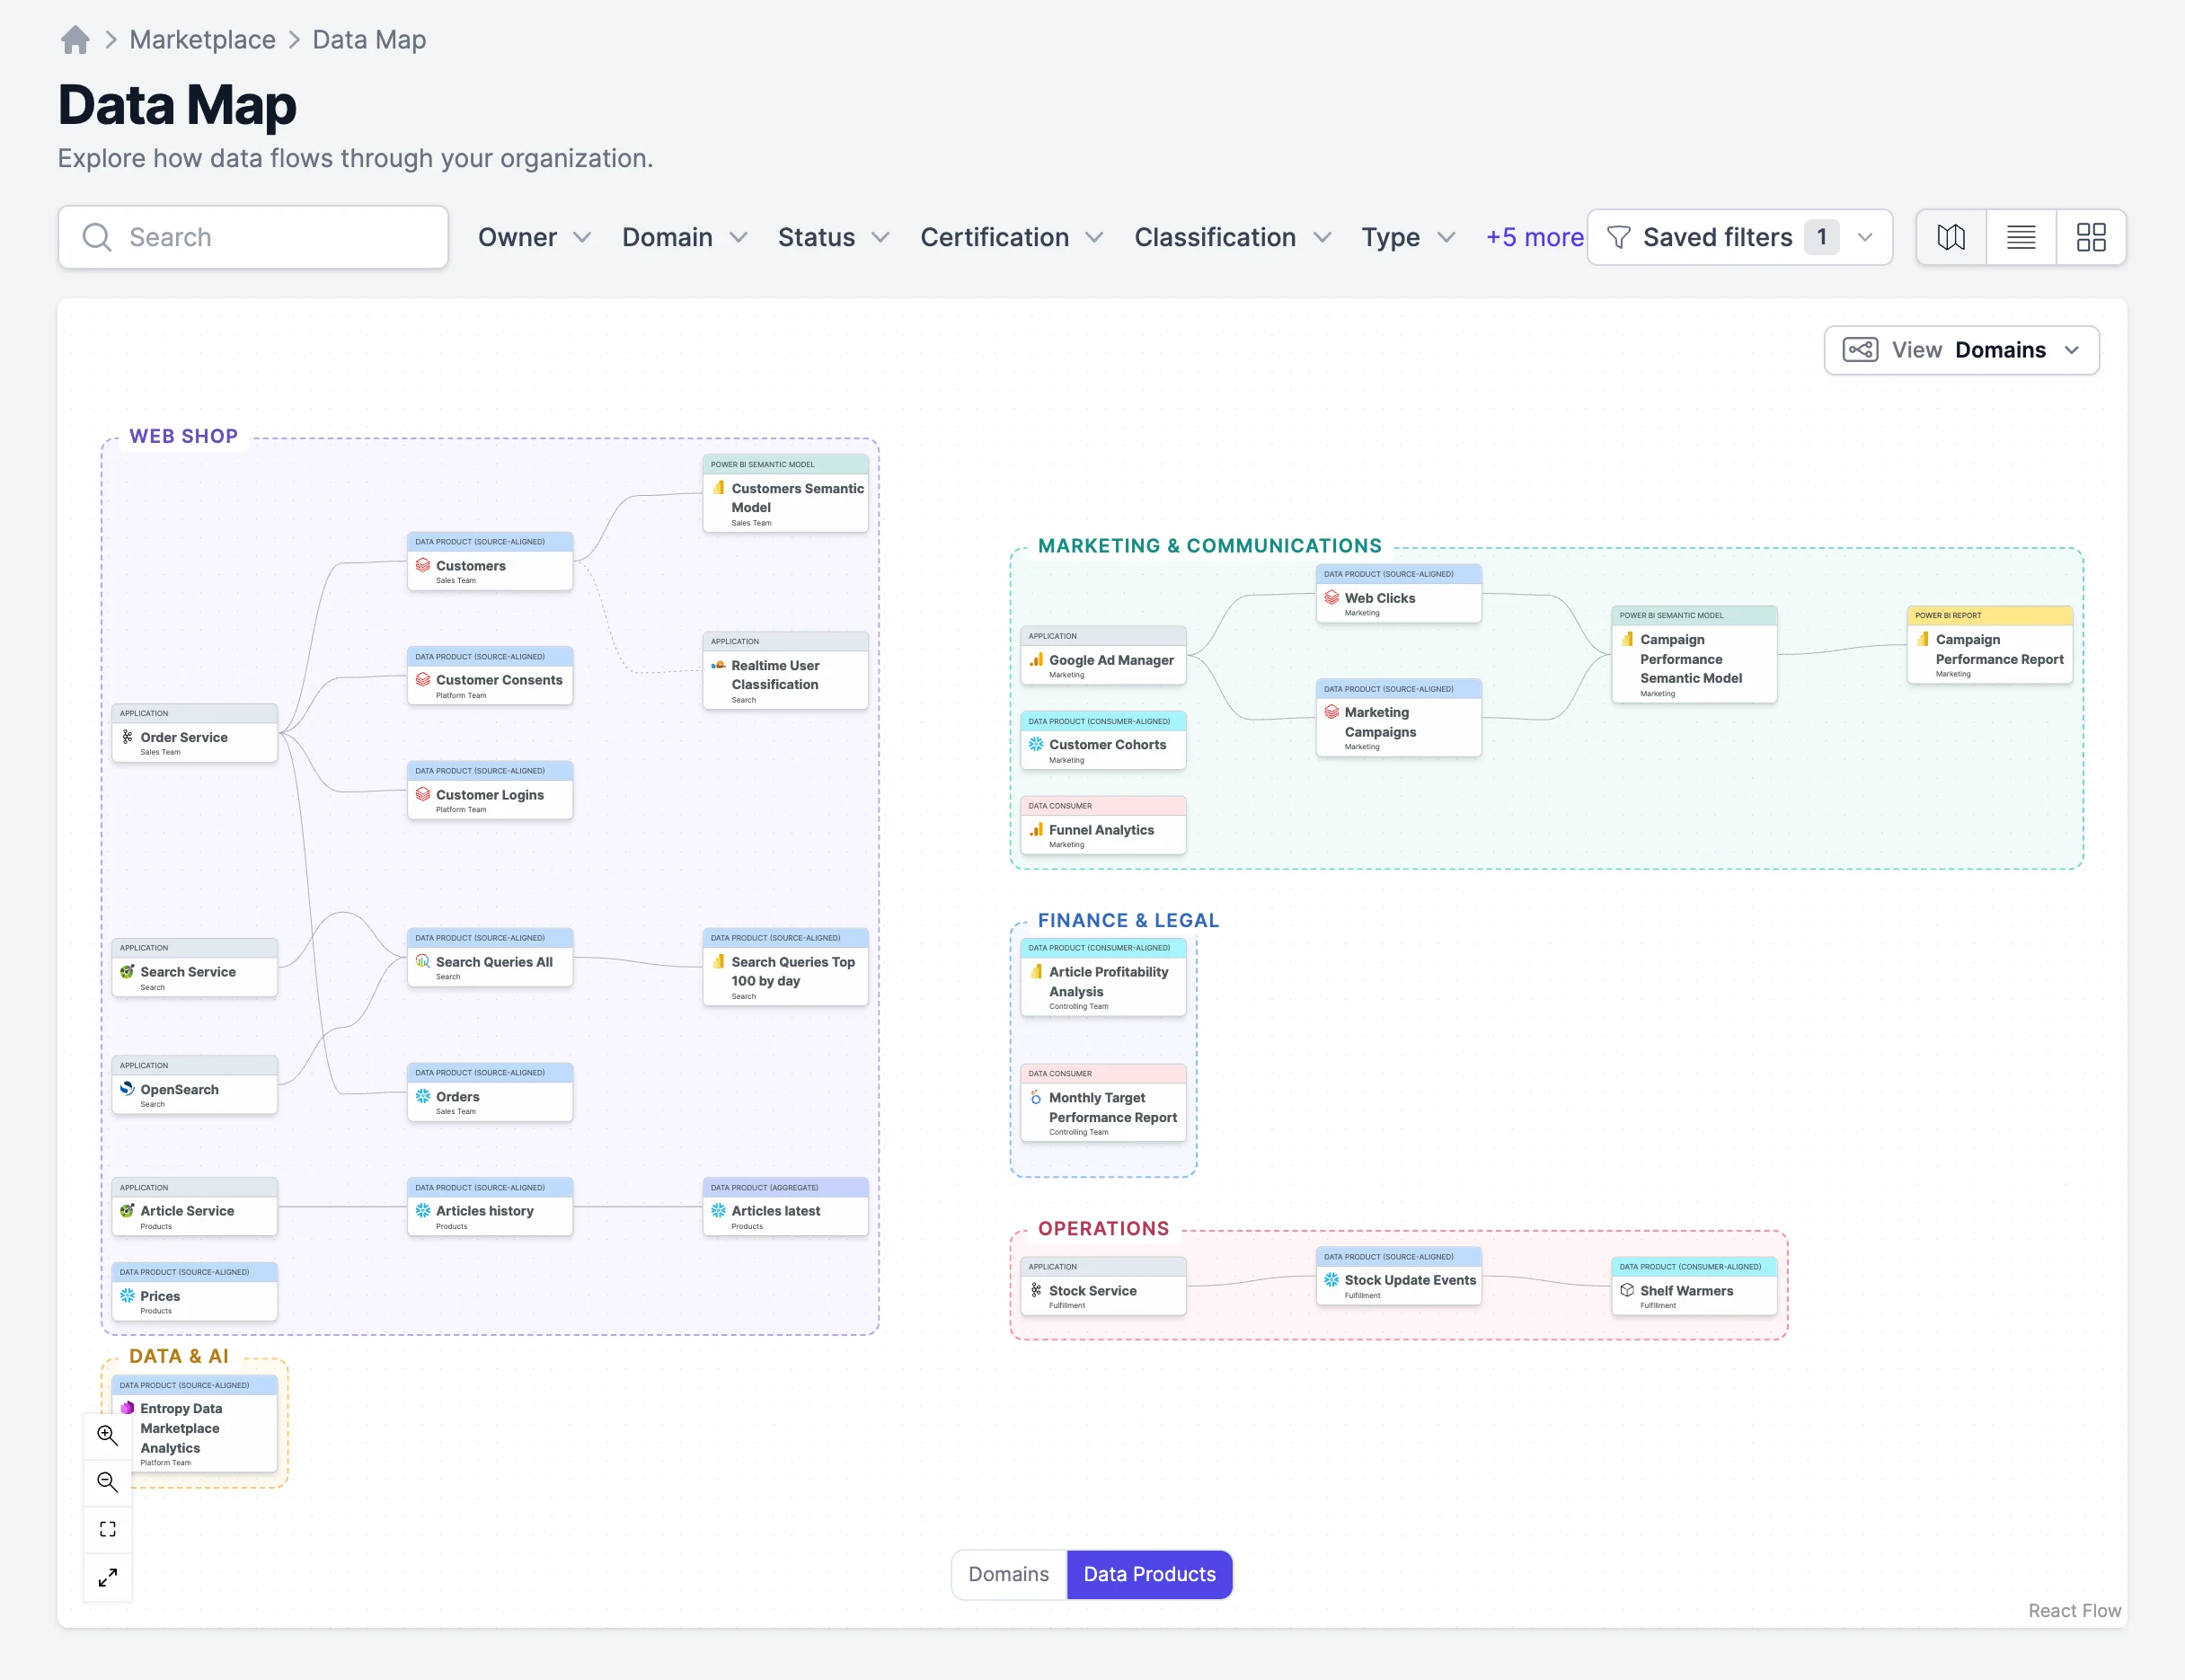
The data map is another way to find data products when you already know which systems and domains are relevant for you. The data map draws every domain with its data products and the flows between them, from the source systems on the left to the reports and semantic models on the right, so a user sees where the customer data comes from, whether there are aggregated data products that might also be interesting, and who else is using them.
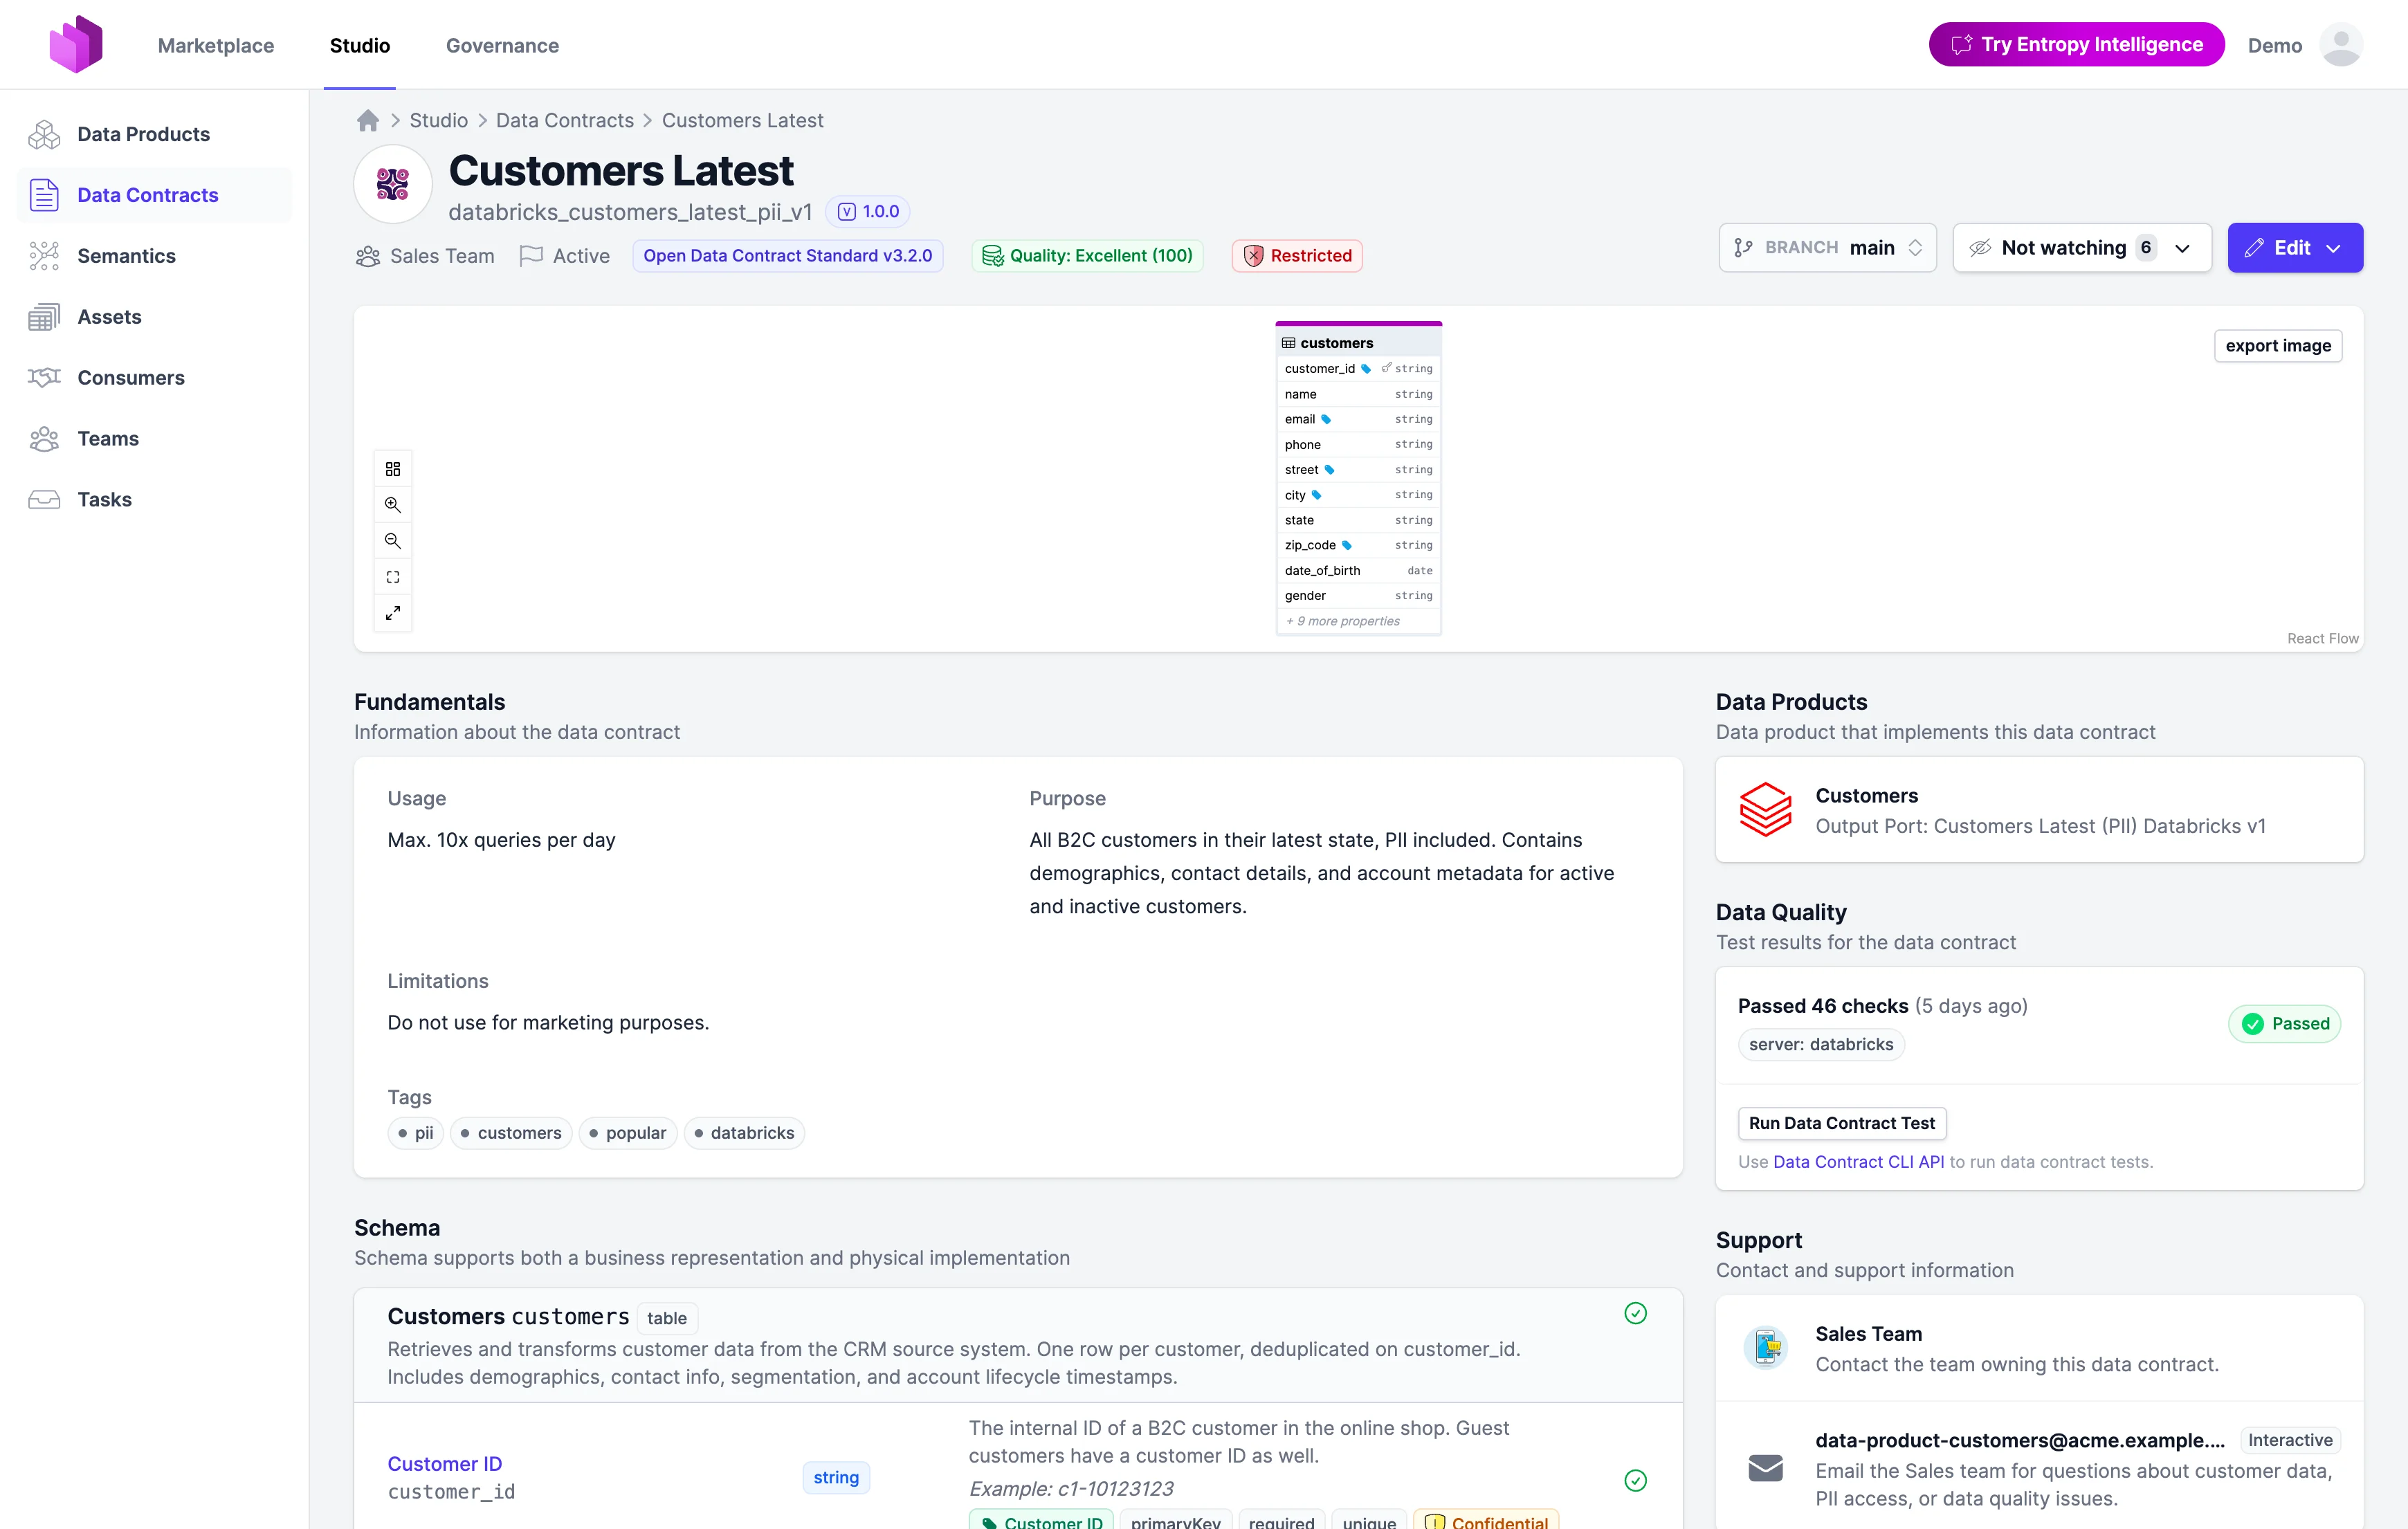
Each data product page is written for the person who wants to use the data. The header tells them at a glance which team owns the product and how to reach that team, which domain it belongs to, whether it is certified, how its data is classified, and how its quality checks are doing, and below it they find the description, the output ports with their data contracts, the lineage, example data, and the terms of use, so they can judge in a few minutes whether the product fits their case before they ask anyone.
When the product fits the business case, the access and approval workflow guides the user through the process to actually get access to the data in Databricks, Power BI, or any other tool they want to use. The user says whom the access is for, themselves, their team, one of their data products, or an AI agent, writes down the purpose (a mandatory field!), and accepts the terms of use of the contract with its purpose and limitations. Entropy Data routes the request to the data product owner to review and approve. When it is approved, Entropy Data (or a custom connector) provisions the permission grants in Databricks, and the access in Power BI or any other tool the user works with.
Of course, more and more agents require access to business data. A data marketplace is the perfect entry point for agents to find data products that are well-documented and of high quality. All features and workflows are designed to be accessible via MCP, APIs, and CLI. In any case, the data product owner stays in control of the data and has an overview of who or what uses which of their data for which purposes.
Databricks offers two marketplace options of its own, but both are quite limited:
-
Databricks Marketplace with private exchanges.
- It was designed as a B2B marketplace to sell data to other companies. Private exchanges limit listings to invited members.
- A member is the Unity Catalog metastore of a Databricks customer, not a team or a person. For teams on the same metastore, Databricks recommends Unity Catalog grants instead.
- Only Marketplace admins can publish listings, so data product owners cannot publish on their own.
- An access request asks for a name, a company, and an intended use in free text, with no contract terms, purpose binding, or expiry.
- Listings carry descriptions, sample notebooks, and links, but no data contract, semantics, or quality checks.
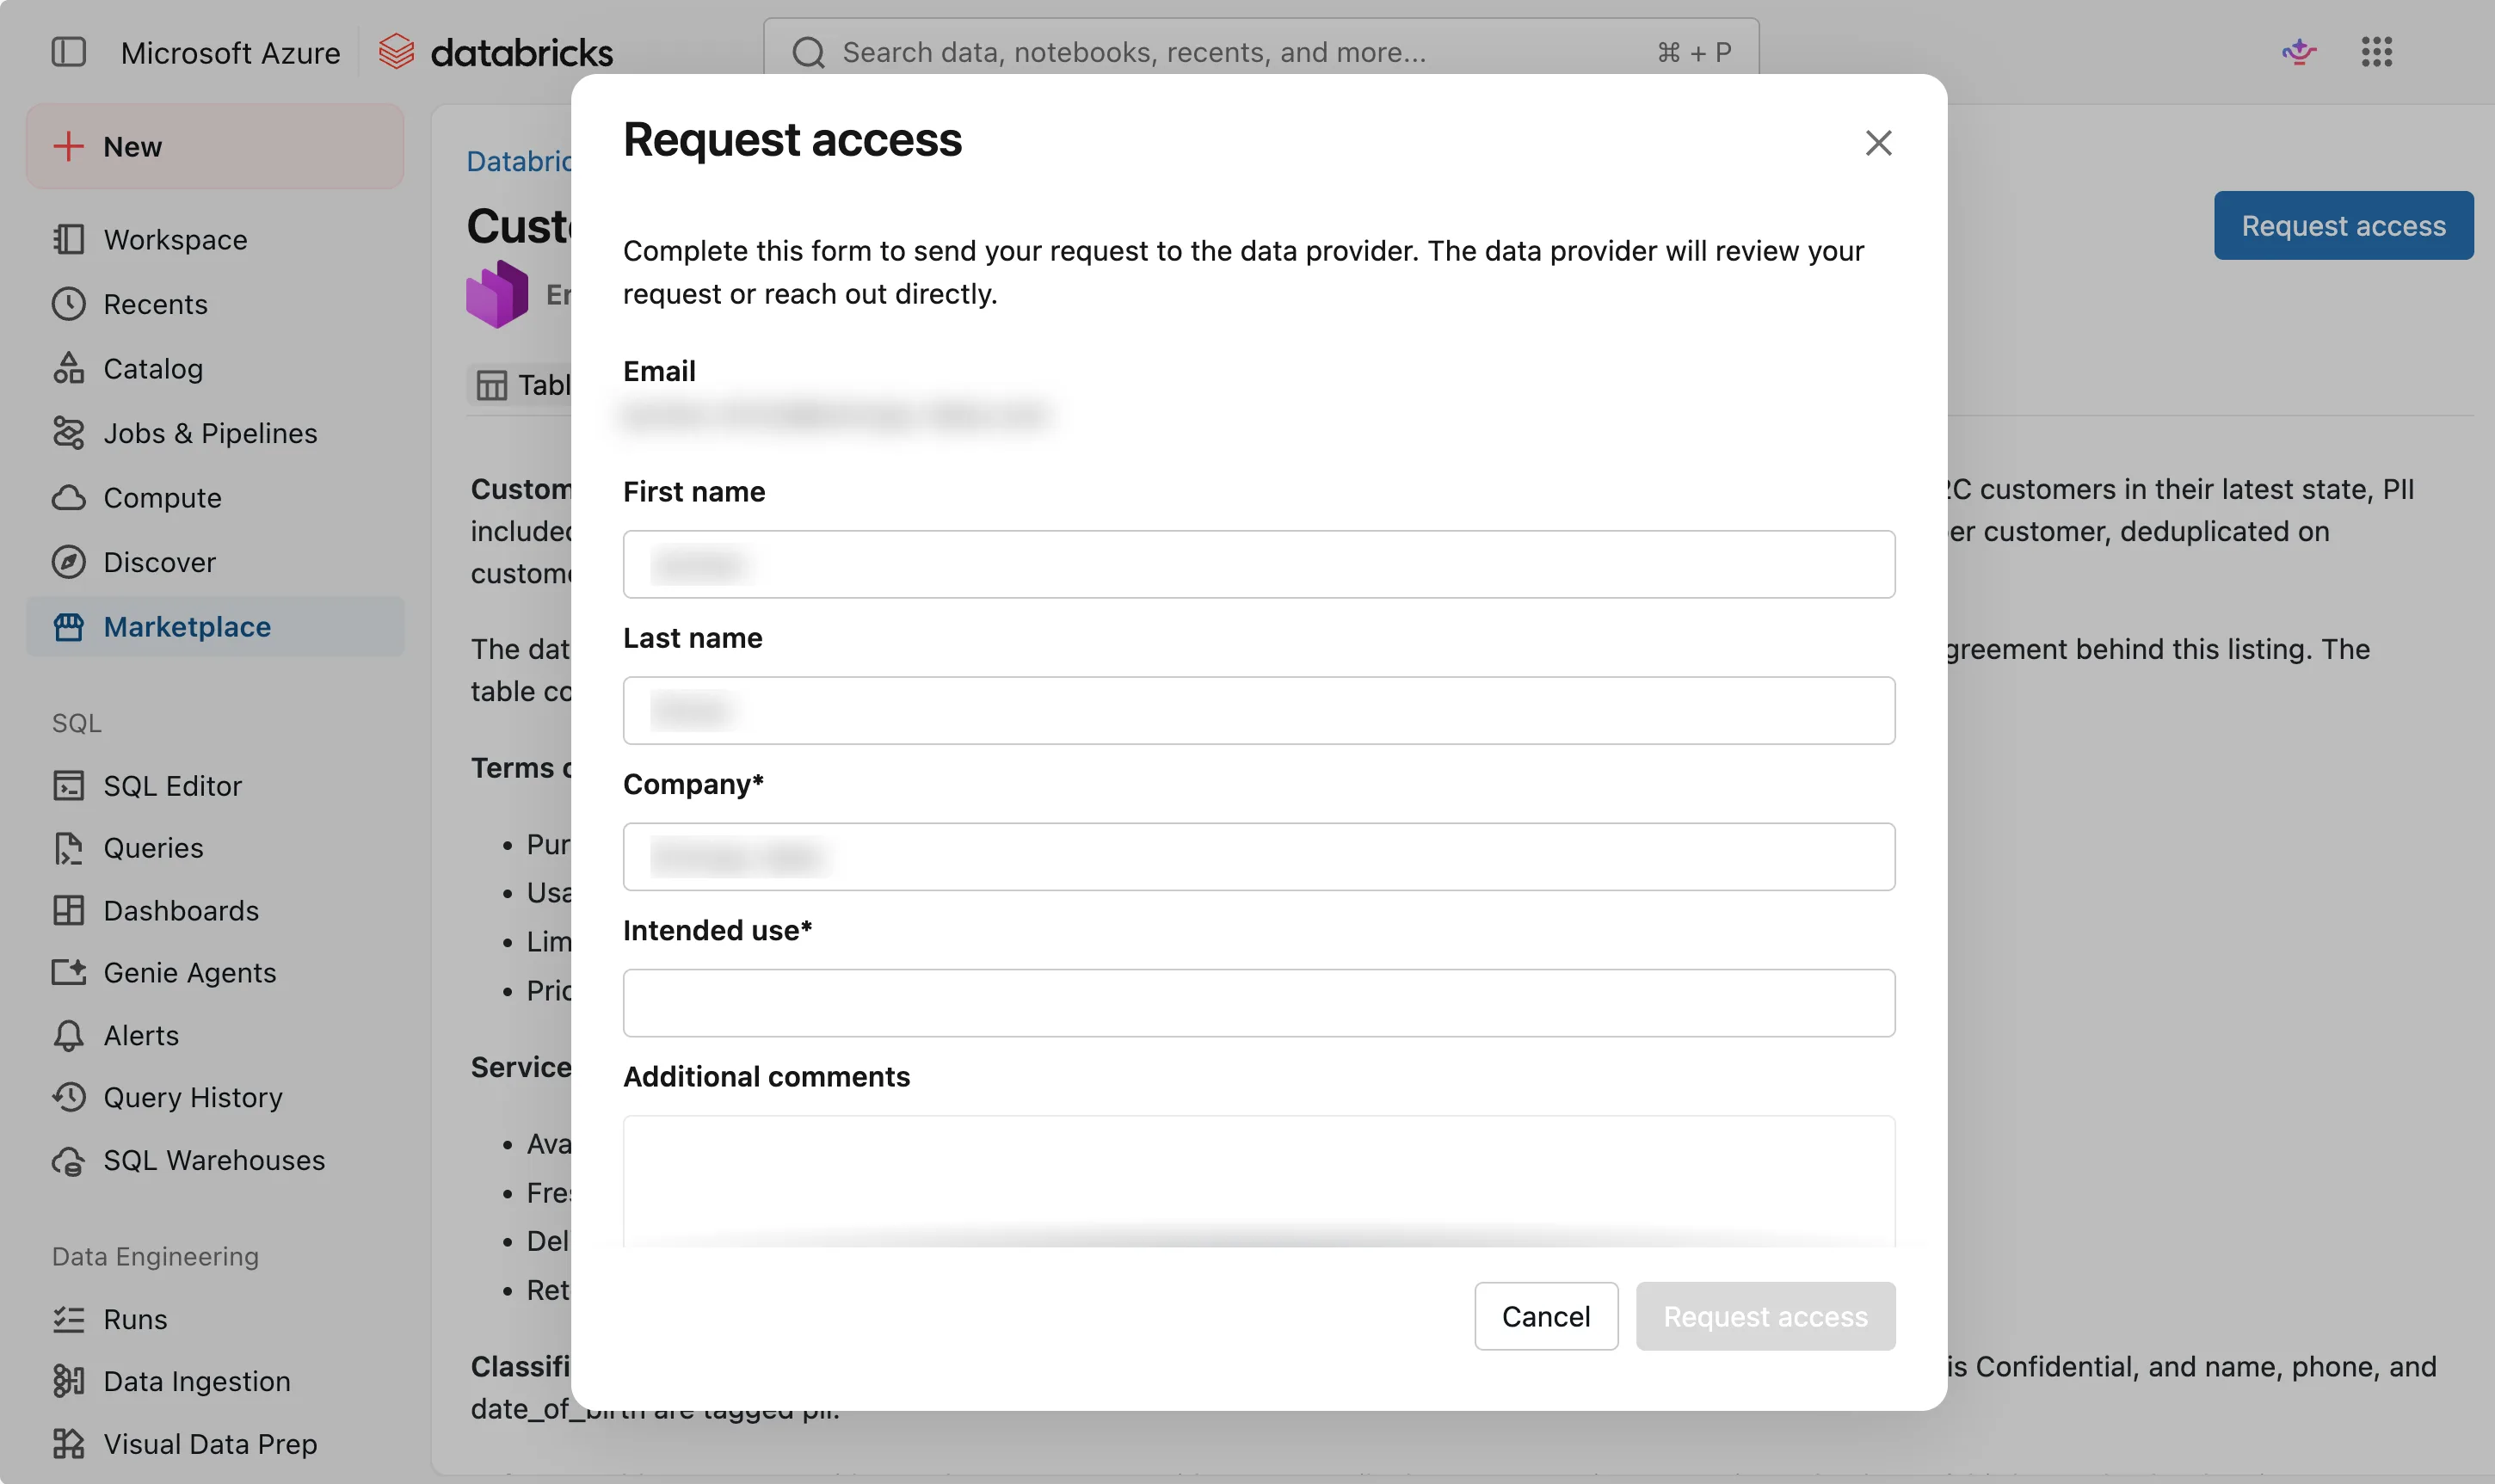
An access request in the Databricks Marketplace asks for a company and an intended use in free text. -
Discover.
- Domains and pages in Discover are just Markdown documents.
- It organizes Databricks assets such as tables, dashboards, notebooks, and metric views.
- It covers only assets in Databricks.
- It lists assets, not data products, with no data contracts or quality guarantees.
- It has no access request or approval workflows.
- Parts are still in Preview or Beta, such as Pages and the glossary.
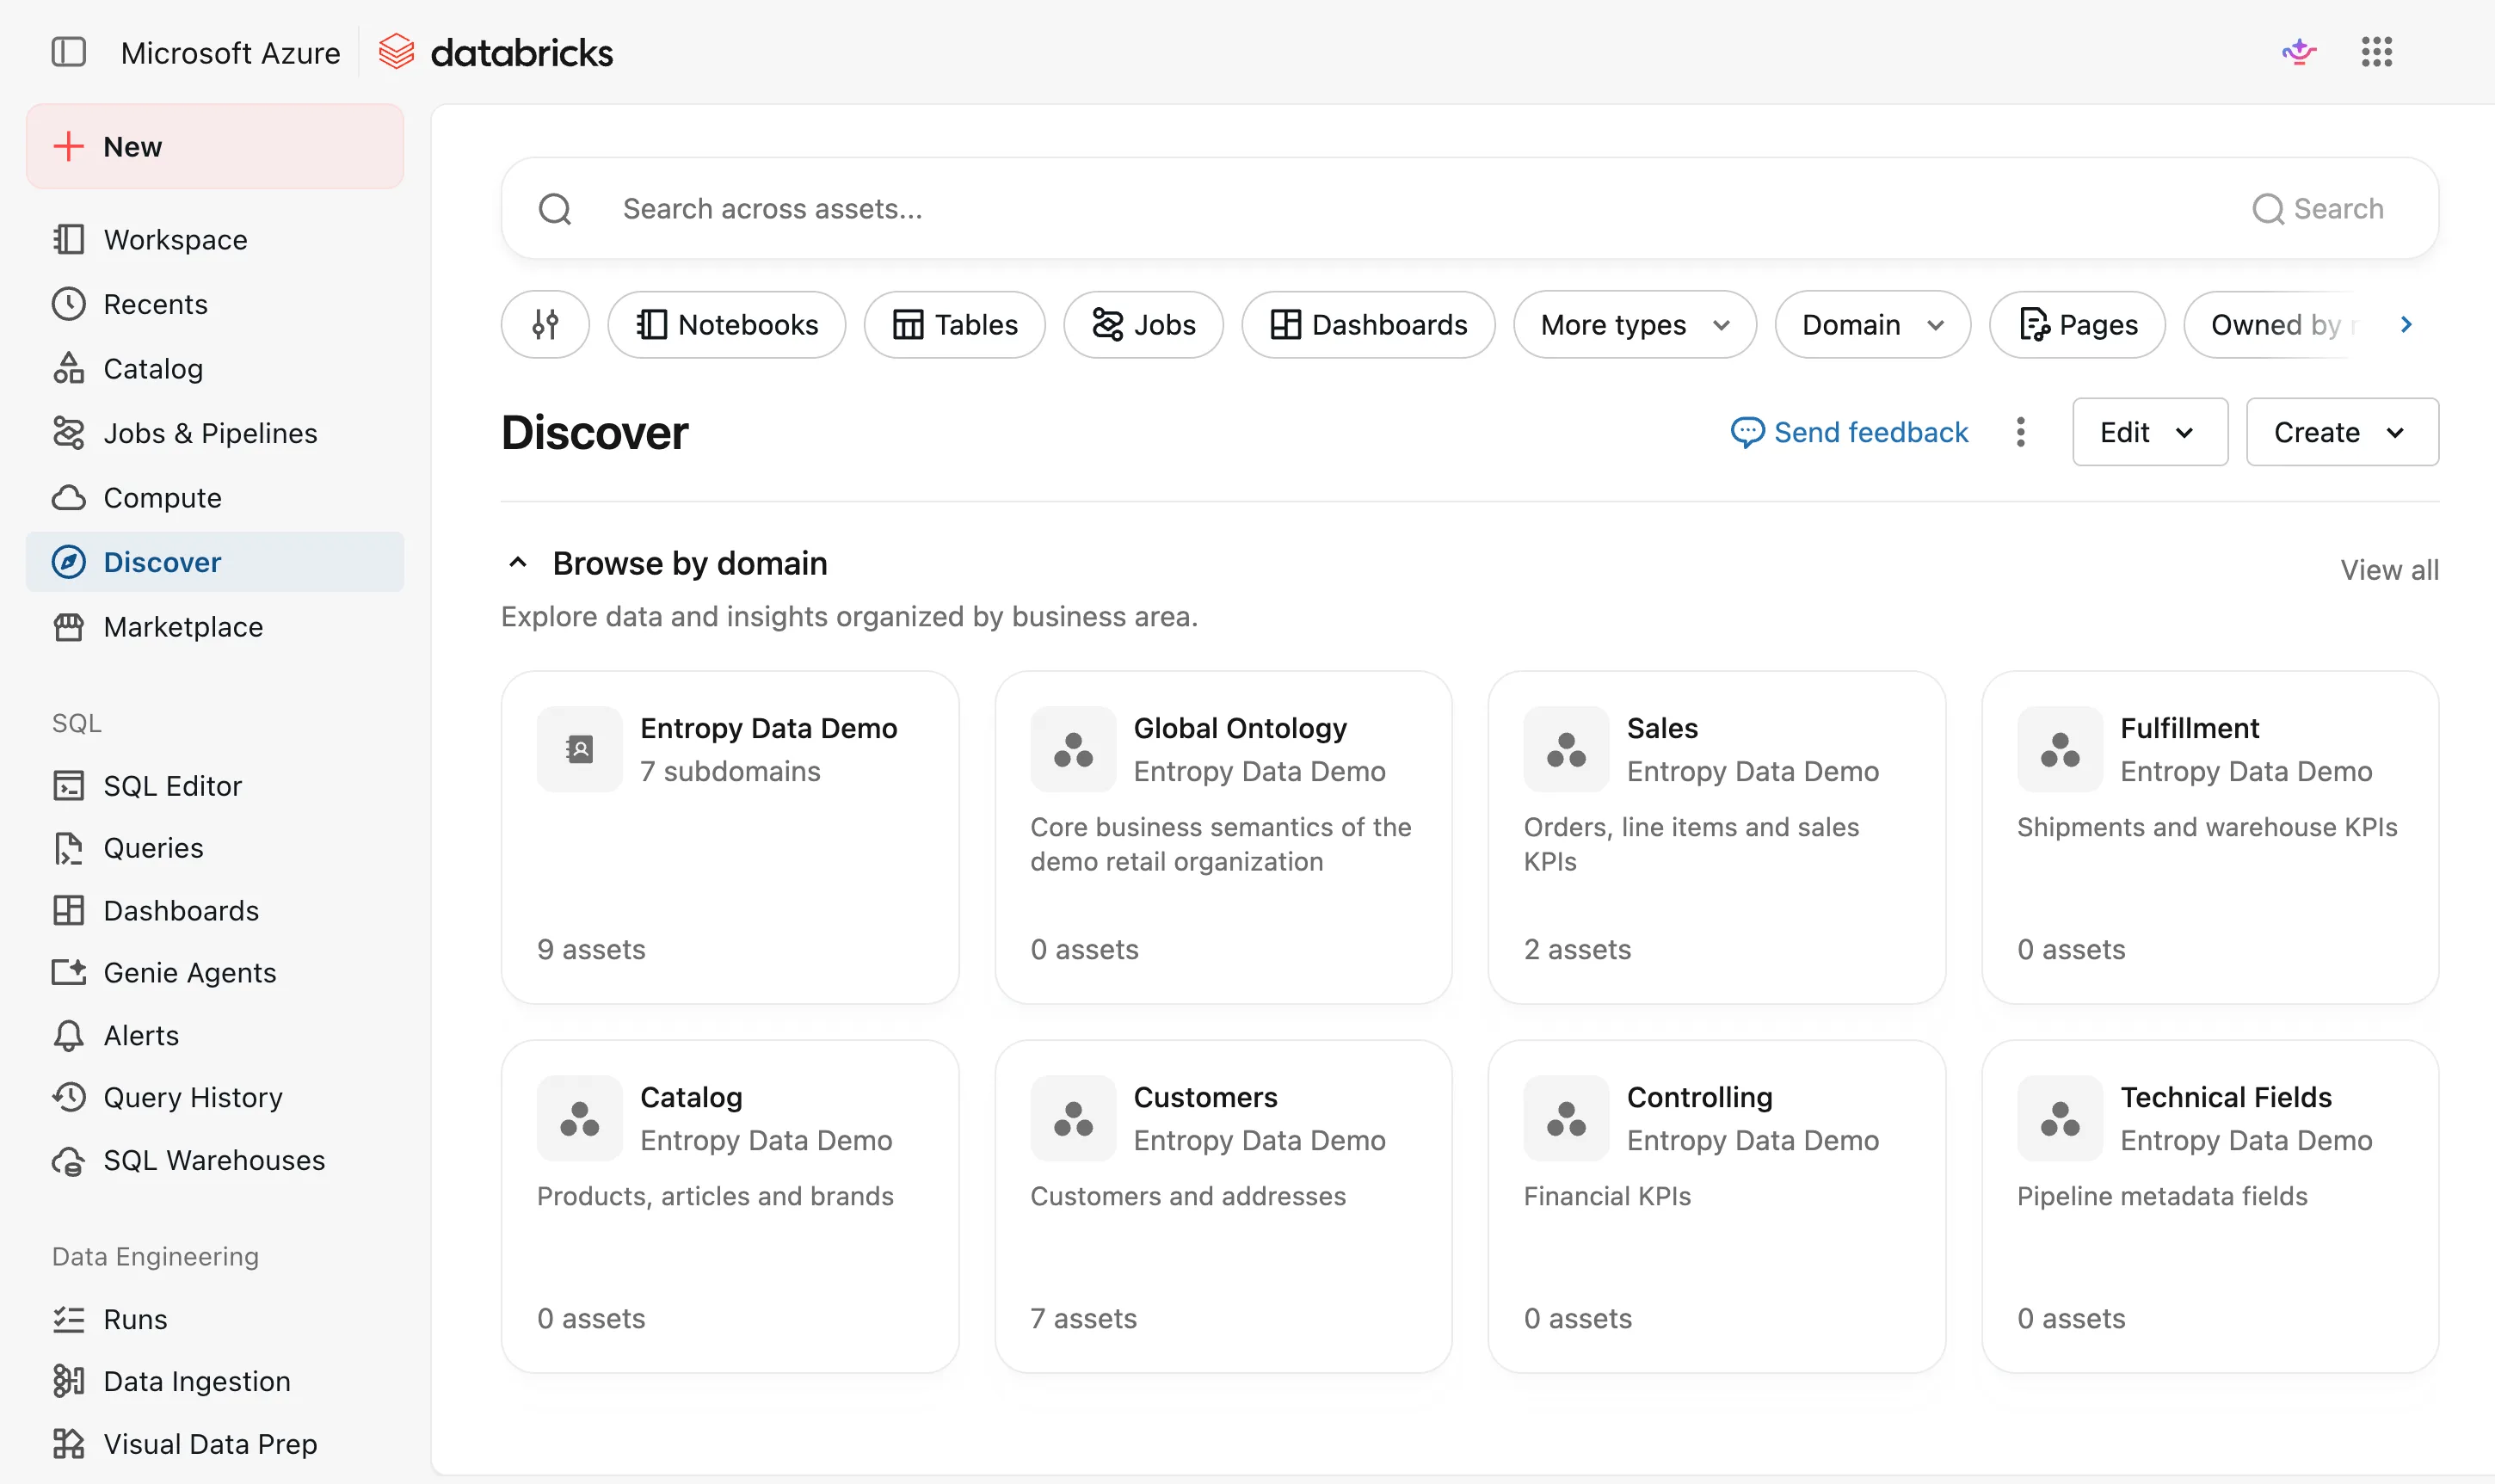
Discover organizes Databricks assets such as tables, notebooks, jobs, and dashboards by domain.
Enterprises have more data platforms than just Databricks: legacy data warehouses, operational systems, SAP, MDM, Kafka, and more. A third-party data marketplace such as Entropy Data can provide access to data in all relevant platforms.
Domain ownership for data products
A table with the rows is not usable data yet. Say you find a customers table in
the catalog and it has the columns you need. But is it the authoritative one, or one of the
three copies other teams made? What does status = 4 mean? Is it refreshed every
night or whenever someone remembers? May you use it for a newsletter? And who do you ask when
a column disappears next month?
The platform cannot answer these from the tables alone. Someone who knows the business has to write it down, and it has to be written down once, where every consumer, human or AI agent, can read it. Without that, every consumer guesses, and AI agents guess even faster.
That is what Entropy Data holds. Data products are the curated tables, exposed as output ports, with everything else hidden. Data contracts describe them with a schema that carries business names and classifications, with terms of use, an SLA, and executable quality rules. Semantics holds the business concepts, Customer, Order, Gross Merchandise Value, with definitions, relationships, and metric formulas, linked from the contract columns. Around all of it sit the owners, the access agreements, and the policies, so it is clear who is responsible, who may use what for which purpose, and what the rules are.
The overall picture
Entropy Data sits above Unity Catalog, so nothing about how you run Databricks changes, while Entropy Data adds the layer in which a table becomes a data product with a contract, an owner, consumers, and a meaning. The two layers are connected in both directions, because Entropy Data reads the assets from Unity Catalog, and whatever the business decides in that upper layer comes back down to the tables as comments, tags, and grants.
Everything in that upper layer is kept in open standards. Data products are stored in ODPS, data contracts in ODCS, semantics in Apache Ossie, and lineage in OpenLineage, all of it YAML you can keep in Git. Databricks gets it as comments and tags, Snowflake, BigQuery, and AWS Glue get the same definitions in their own vocabulary, and your AI agents read it over MCP. That matters because hardly any organization runs on one platform. About 60 percent of Databricks accounts also run Snowflake, according to an ETR survey of 1,800 IT decision makers, and the warehouse that came with the ERP, the BI tool, and a message broker add to the list. Replace a platform, and the definitions stay.
Read from Databricks, write back to Databricks and to all your other platforms
Entropy Data reads the catalogs, schemas, tables, views, and columns of your Unity Catalog as assets, through a built-in ingestion that runs on a schedule.
An asset is not a data product yet. Take your orders team. It has forty tables in its schema,
and four of them are the curated result. You pick the four, and they become the output port
of the Orders data product. The other thirty-six stay internal. Entropy Data drafts the data
contract from the asset, so the physical columns are already there, and you add what the
catalog cannot know, such as what customer_id means, how fresh the data is, and
what it may be used for.
Then the metadata flows back through the
metadata writer.
Whenever an active contract changes, Entropy Data writes the
descriptions of the contract's tables and columns as table and column comments in Unity
Catalog, and the contract's tags, classifications included, as table and column tags. A column
without a description of its own gets the description of its linked concept. Two more tags,
entropy_data_contract and entropy_data_concept, link back to the
contract and the concept. Whoever finds the table in Catalog Explorer, Genie included, reads
the definition your business agreed on and can jump to its source.
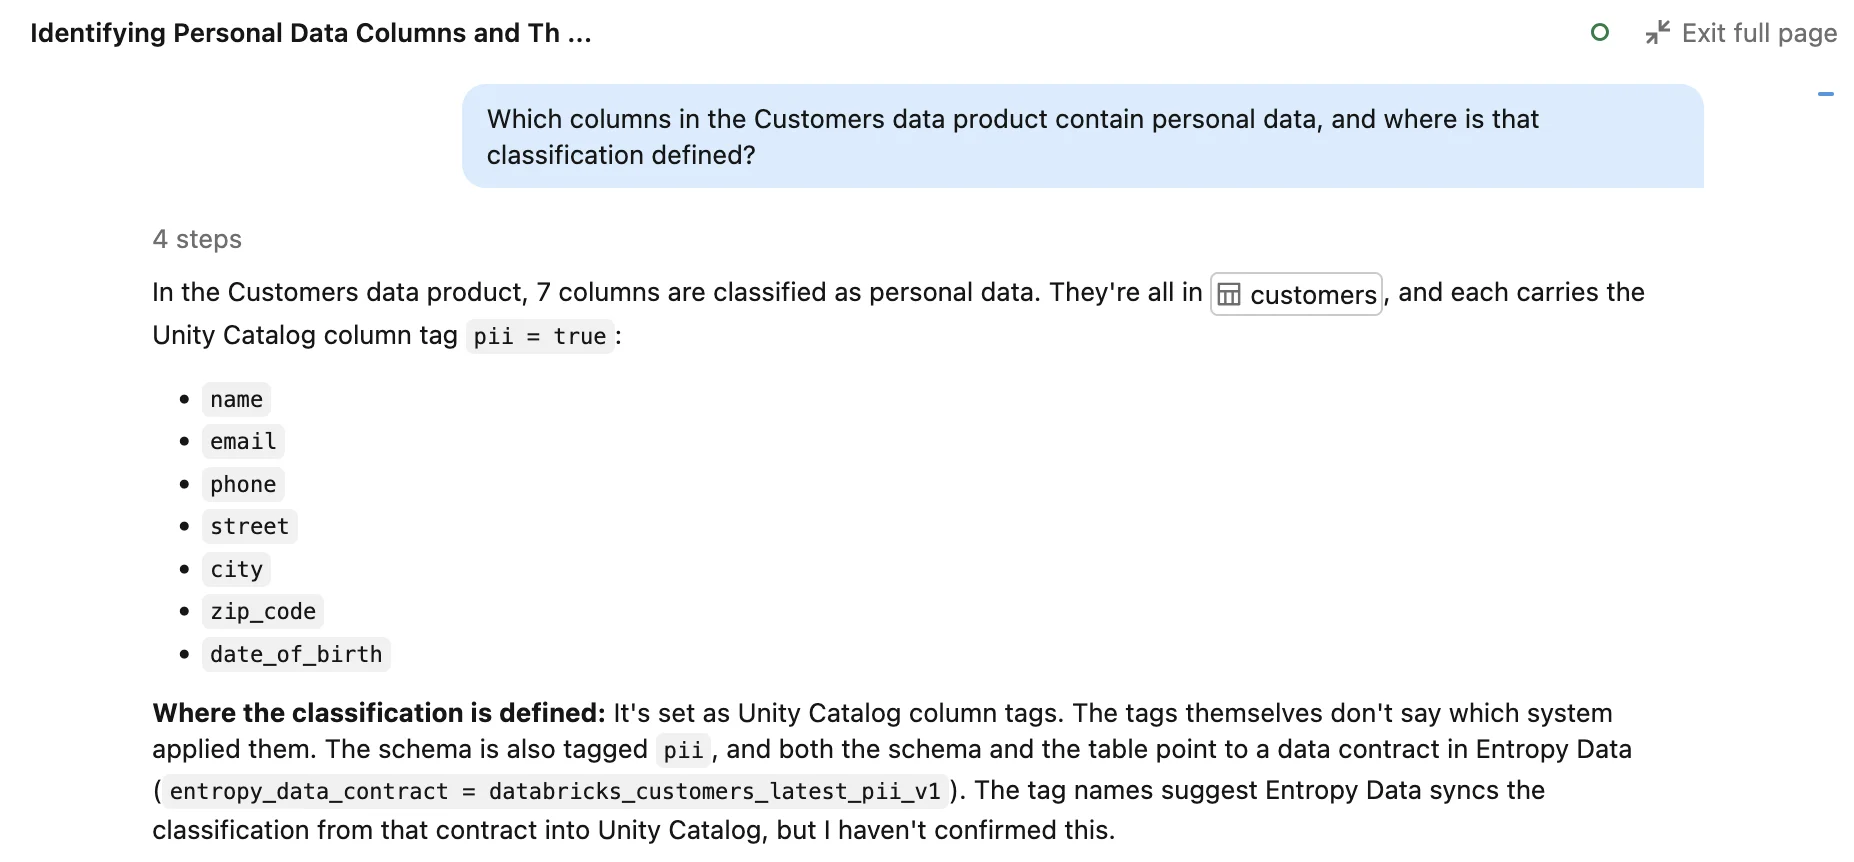
Quality rules take the other direction. A Databricks job runs the Data Contract CLI against the output port and publishes the results to the contract. The Data Quality Score tracks the trend, and you and your consumers get a notification when a check fails or recovers. A schema change that breaks the agreement shows up as a failed check, before a consumer notices.
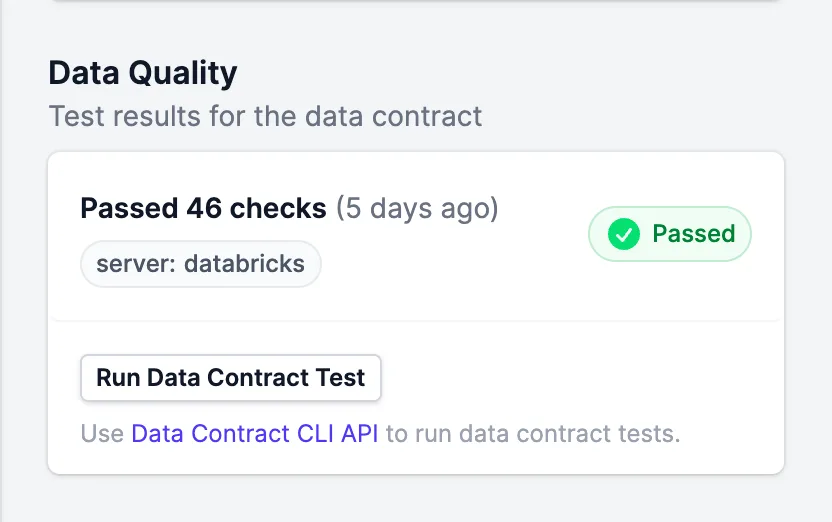
In Databricks you see comments and tags on tables and columns, maintained by Entropy Data, and a job that runs the checks on your compute.
Semantics give every column a meaning
A contract says that email is a string and may not be used for marketing. It does
not say what a customer is, whether the customer in the Orders product is the same as the one
in the CRM export, or how Gross Merchandise Value is calculated. That is the job of
semantics. Business concepts such as Customer, Order, and Gross
Merchandise Value live in a namespace with a definition, their properties, their
relationships, and metric formulas, written in Apache Ossie YAML and owned by a team like
everything else.
Contract columns link to these concepts. A column that links to Customer Email inherits its description, its classification, and its validation rule, so the definition is written once and a change reaches every contract that uses it. The reverse lookup answers the question a privacy officer asks first, which data products contain customer email addresses. Colleagues and AI agents propose changes on a branch, domain experts review them in the UI, and the merge lands in every contract.
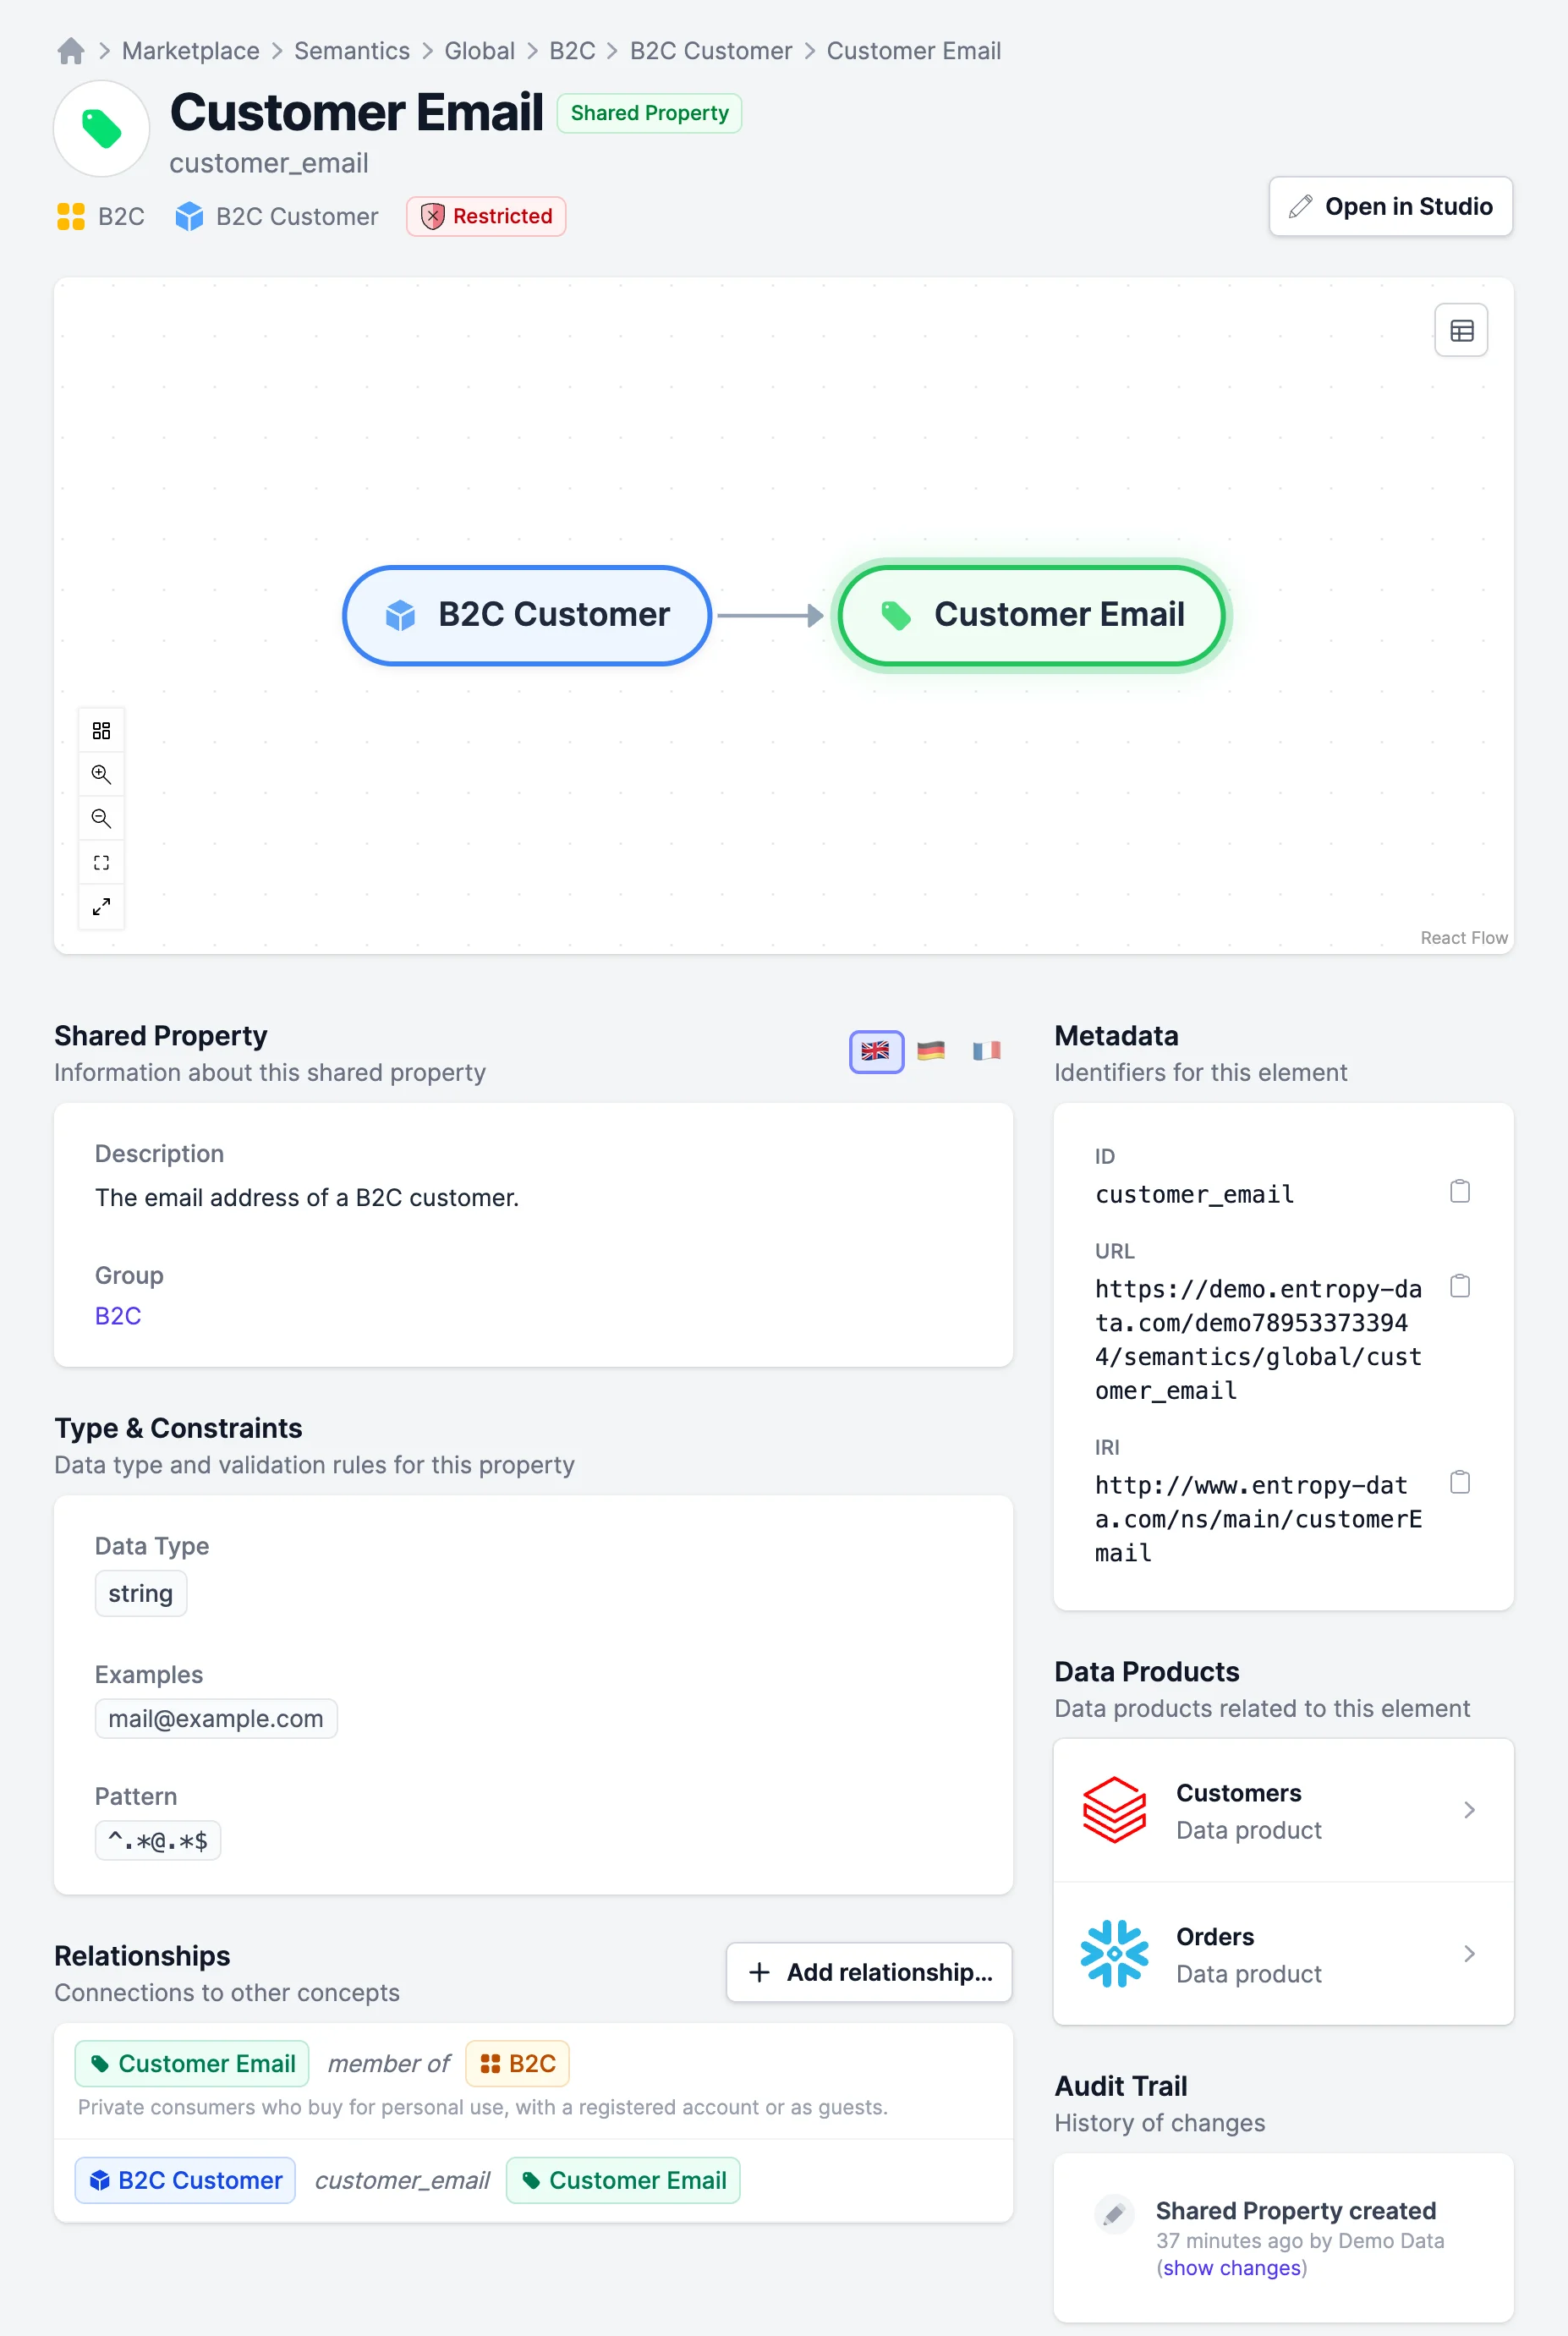
In Databricks, the concept arrives as the column comment where the contract has
none of its own, and as the tags entropy_data_concept and
entropy_data_concept_url, so Catalog Explorer and Genie show the agreed
definition and link back to it. Once Databricks Pages have an API, the concepts will be
written there as well.
Ownership
A table in Unity Catalog has an owner for its privileges. A data product needs an owner for its promises, someone who answers questions, approves access, and fixes the pipeline when a check fails.
In Entropy Data, a team is the smallest unit of ownership. Every data product, data contract, and semantic namespace belongs to a team, teams belong to domains, and roles are inherited down the hierarchy. Consumers see who is responsible and how to reach you on every product page.
Access requests go to the people with the Approver role on your team. Quality
alerts reach you and the consumers who watch the contract. Change requests for your products
land in your inbox. And the
Data Product Score
shows which products still lack an owner, a description, or a contract. We wrote down the
reasoning in The 4 Principles of Data Ownership.
In Databricks, the catalog owner stays the technical owner of the objects. The business owner, the team, and their roles live in Entropy Data, where the requests arrive.
Access for humans and agents
A consumer who has found a data product in the marketplace and read its contract requests access with a purpose and accepts the terms of use as part of the request, and your team approves or rejects it with an AI evaluation of the request against those terms right next to the buttons, while every step lands in the audit trail. Where a manual decision adds nothing, access can be auto-approved per output port, and where you already run an approval workflow, it can take over through the API.
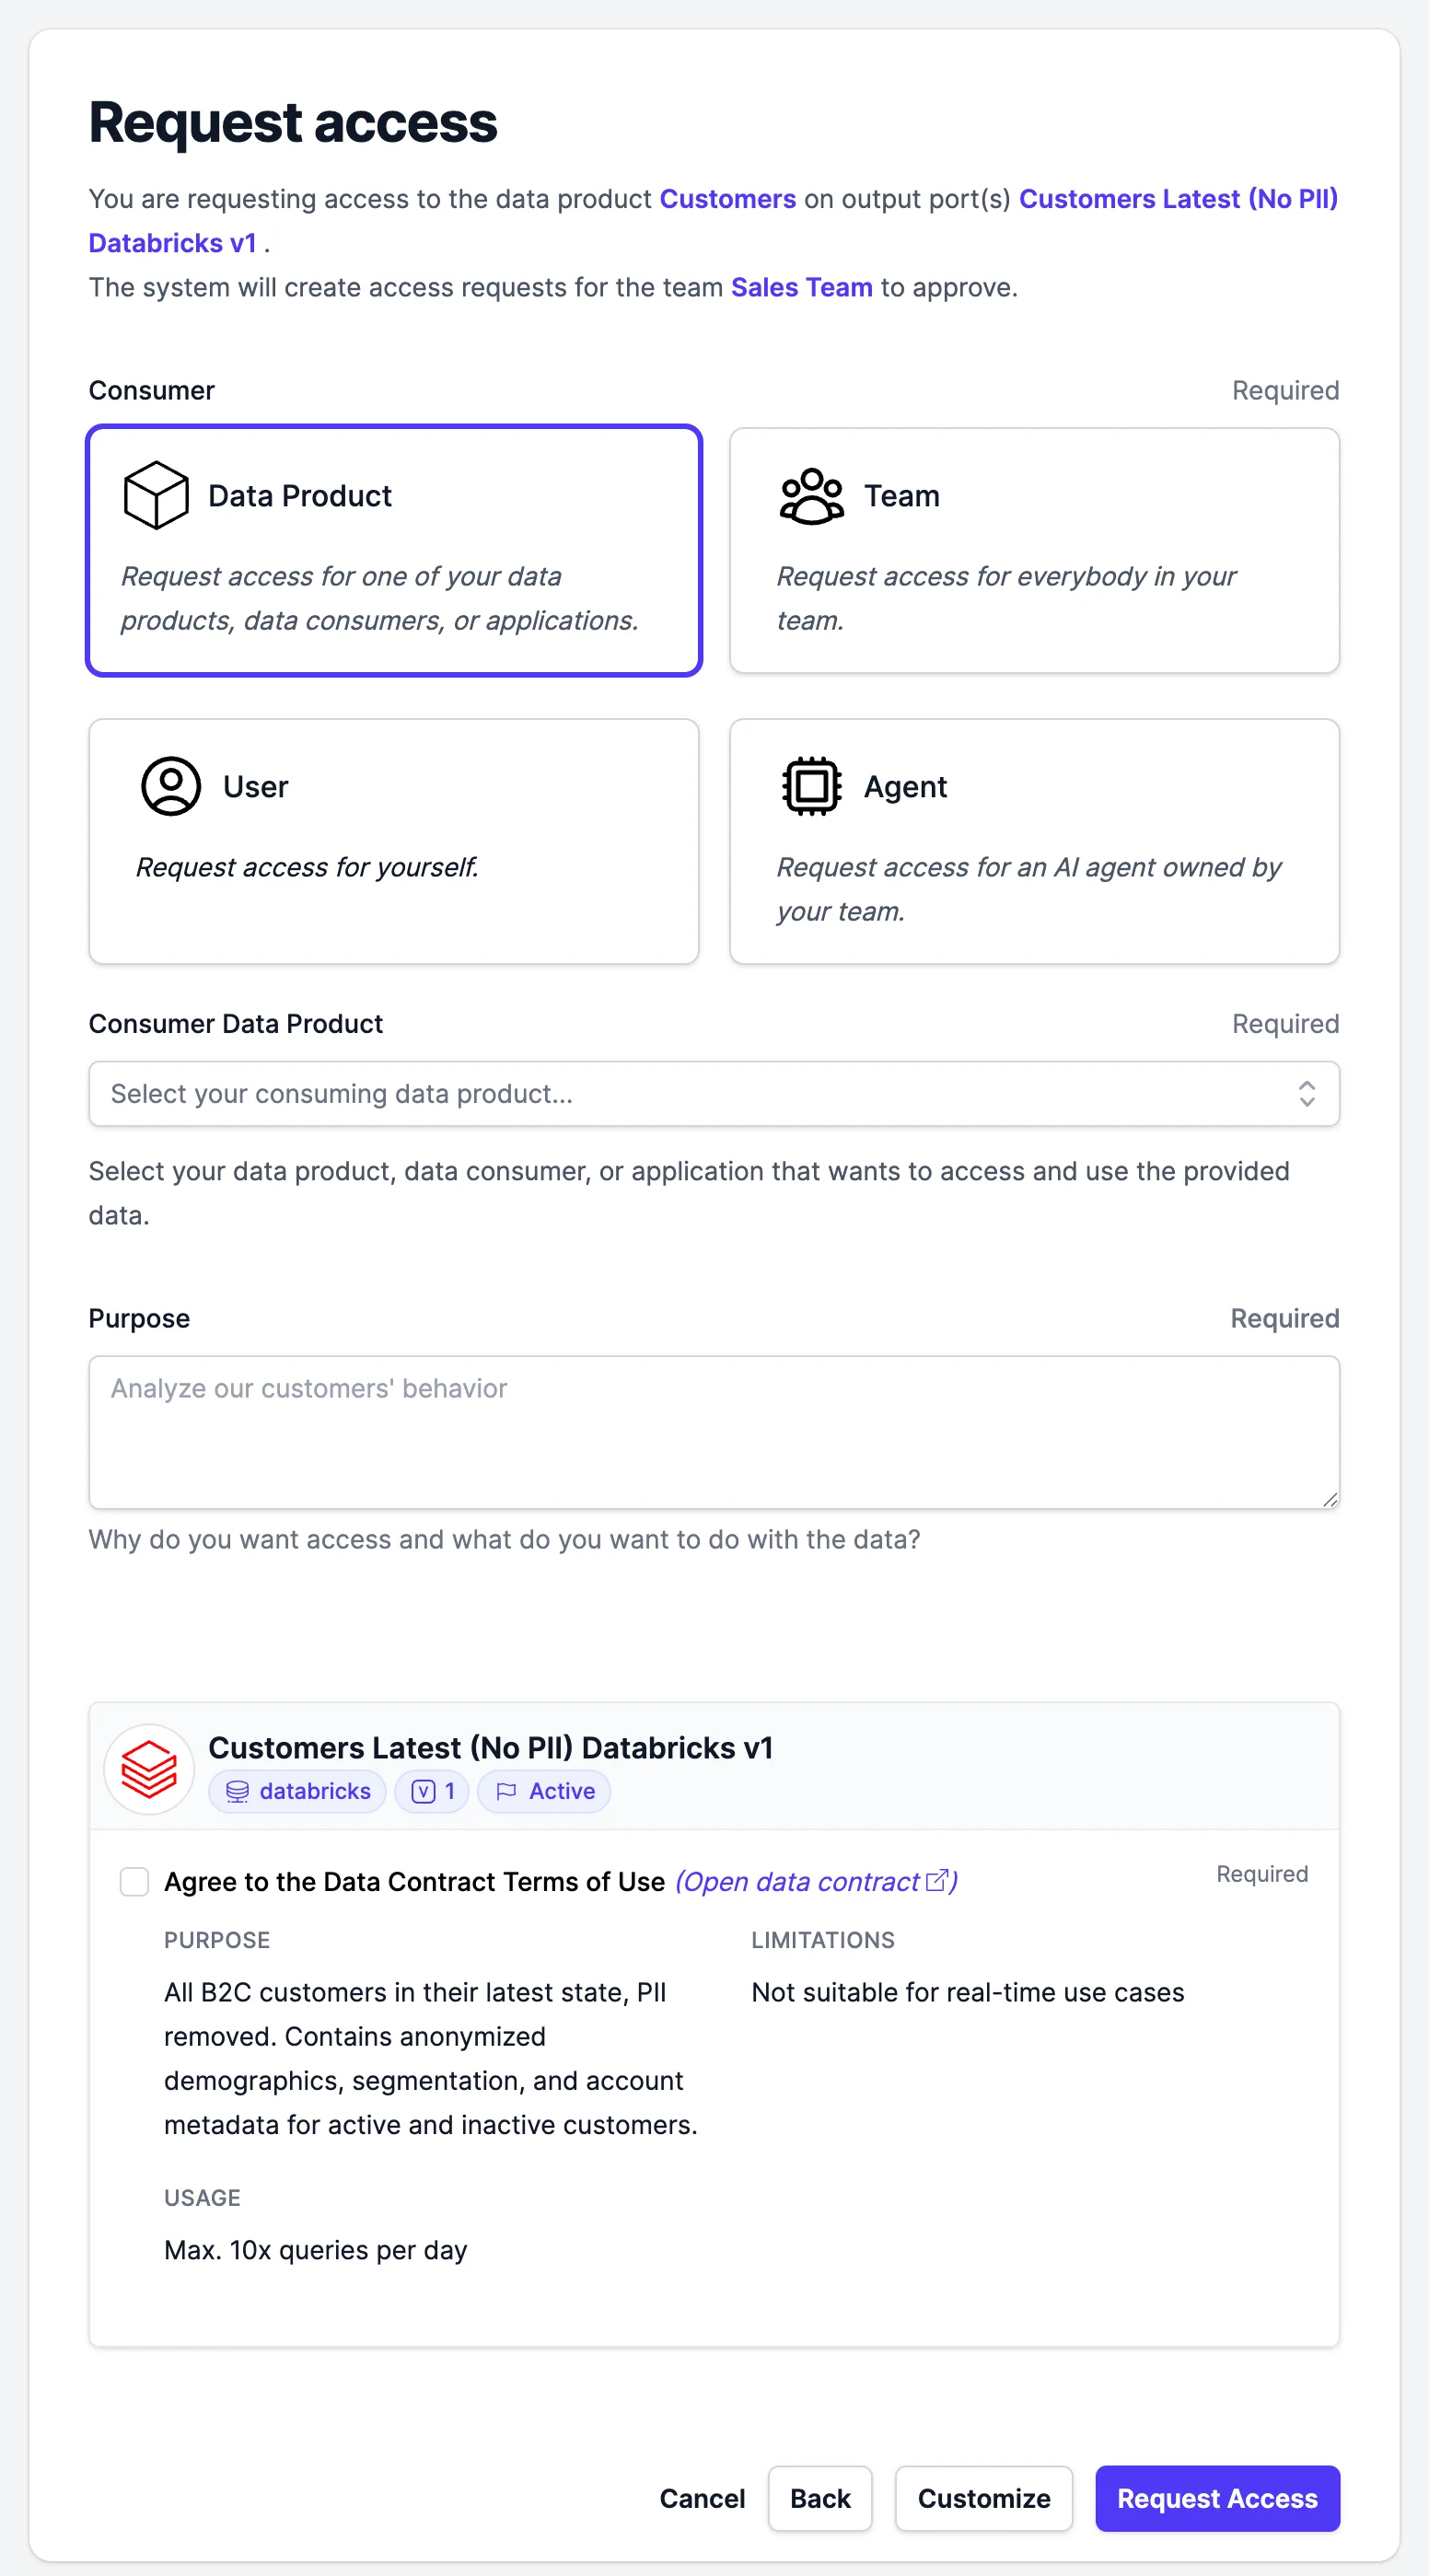
Today, the consumer is not necessarily a person. A request can come from a user with their company SSO account, from a team so that everyone on it gets access at once, from another data product that builds on this one, or from an AI agent with an identity of its own, and none of them needs a Databricks account to browse the marketplace and ask. What they asked for is also what they get, because purpose-based access control checks at query time that the data is used for the purpose that was approved.
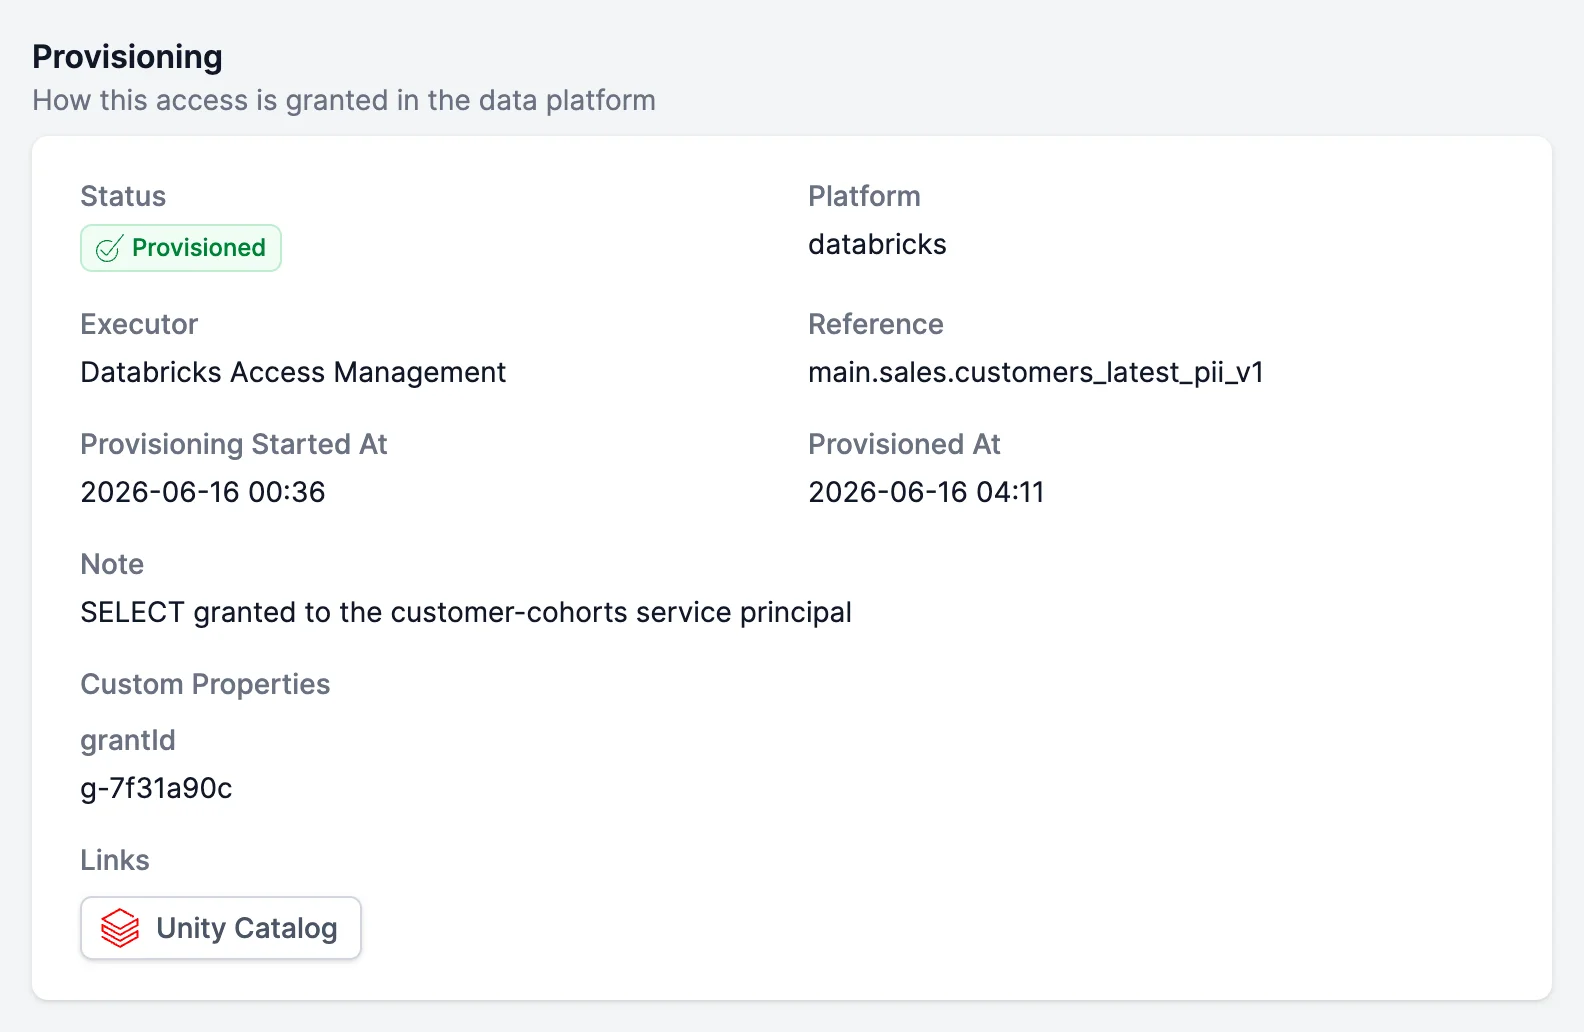
Once the access agreement is active, the Entropy Data access writer turns it into permissions in Unity Catalog, so the consumer can read the tables the contract covers, and only those. The permissions follow the contract when a table is added, they disappear when the access expires, is canceled, or is terminated, and the provisioning status is reported back to the agreement, so what Entropy Data shows as active is what Unity Catalog enforces.
Governance
Governing tables does not scale, because a platform holds millions of them and a rule such as "every dataset with personal data has a retention period" cannot be checked table by table, whereas an organization has a few hundred data products, each with a contract that states what it contains and a team that answers for it, which is a number governance can actually work with.
Entropy Data governs at the level of products, contracts, and access agreements, and the tables underneath them inherit the result. Policies are written in plain language, and Data Governance AI checks every product and contract against them continuously and reports its findings to the owner, who stays in charge of the fix. Certifications with defined criteria mark the products consumers can rely on, while classifications such as GDPR categories are derived from the contract and the linked concepts and inherited by every column that carries the concept, so nobody tags personal data column by column. The terms of use a consumer accepted when requesting access are enforced when the data is queried, every change is kept in the audit trail with a side-by-side comparison, and an optional change process requires approval before a product or contract changes at all.
The Data Product Score is where you define what a good data product looks like in your organization. It rates every product against rules grouped by the FAIR principles, such as a description of a useful length, an owner, a contract, recent test results, and example data, and you weight the rules, scope them to product types, or add your own as expressions or as instructions an AI judges. The leaderboard under Governance then ranks every product and names the biggest gap of each one, which brings a bit of gamification into governance, because teams see where they stand next to the others and what one change would move them up, and the team and domain averages make it visible where to help.
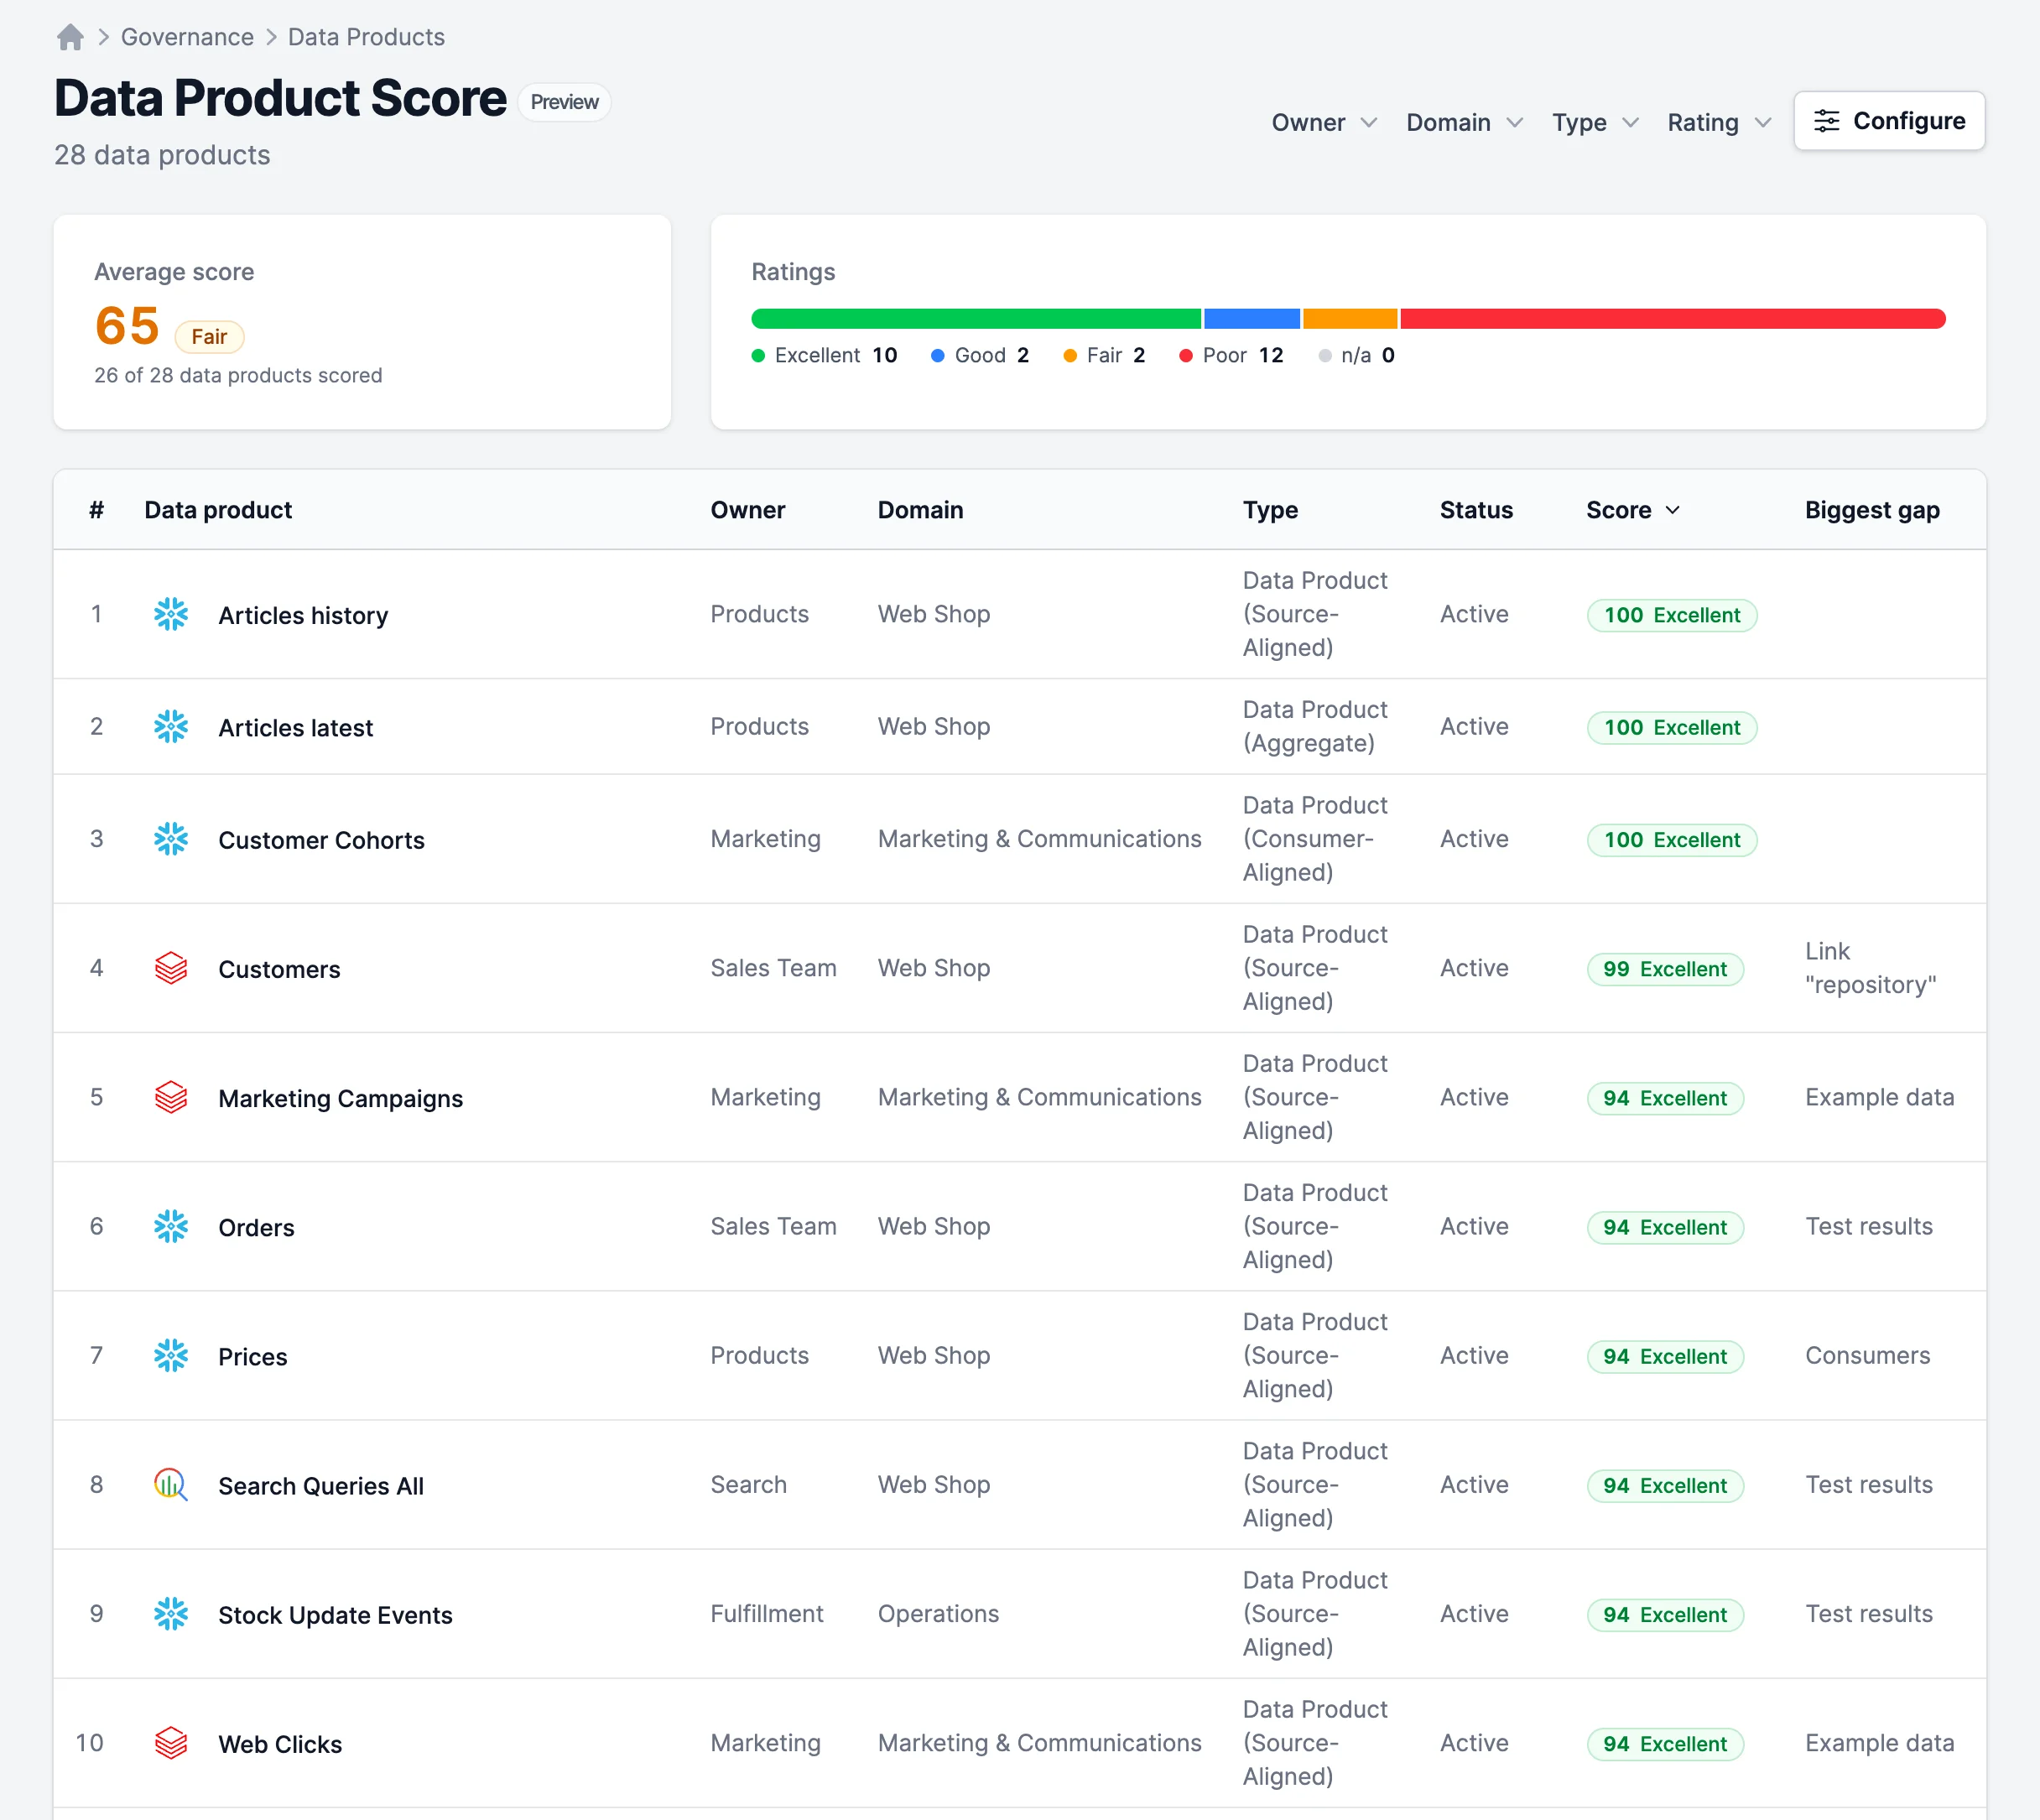
In Databricks, classifications and certifications arrive as tags, and access decisions arrive as grants, while the policy, the reasoning, and the history stay in one place.
Everything is an API
A business view that only exists in a UI would be one more place to maintain by hand, so everything you see in Entropy Data is also an API, and the layer fits into the tooling you already run. The REST API covers data products, contracts, semantics, access, teams, policies, and test results. Two command-line tools bring it into CI pipelines. The open-source Data Contract CLI lints a contract, runs its quality checks against the Databricks output port, and publishes both the contract and the results to Entropy Data, while the Entropy Data CLI works on the organization as a whole, exporting and applying data products, contracts, semantics, teams, and settings as YAML, or syncing them from one instance to another.
Contracts, products, and semantic namespaces can be synced with GitHub, GitLab, Azure DevOps, or Bitbucket, so changes arrive as pull requests and go through the review your code already gets, and an event feed turns every access that is activated, deactivated, or provisioned into something your own systems can react to. AI agents get the same business view through an MCP server, with the same access rules a person has in the UI, and users, teams, and roles come from your identity provider through SCIM and SSO.
In a typical setup, the contract lives in Git, a Databricks job runs the Data Contract CLI to test it and publish the contract and the results, and your agents read the whole thing over MCP, while the UI is where people request, approve, and look things up.
Entropy Data works across all your app, data, and AI platforms
Databricks was the example on this page, but nothing above is specific to it. Entropy Data reads assets from Snowflake, BigQuery, AWS Glue and S3 Tables, Microsoft Fabric, Redshift, Trino, and the other platforms you run, it writes the same descriptions and tags back to Snowflake, the BigQuery Knowledge Catalog, and AWS Glue in each one's own vocabulary, and it provisions access through open-source connectors where the platform has no native writer yet. The integrations page keeps the current list.
That is what makes the layer above the platforms worth having. A data product with an output port on Databricks and another on Snowflake is one product with one owner, one contract, and one set of definitions, and whatever changes in Entropy Data lands in both places at once, while a consumer who requests access does not have to know, or care, which platform holds the tables.
What to do where
The short version of this article is a split of responsibilities, with each side handing the other what it needs. The highlighted cell shows where a task lives.
| What you want to do | Databricks | Entropy Data |
|---|---|---|
| Store, process, and query the data | Primary place. The tables never leave Unity Catalog. | Reads the assets and links back to them, and lets you query the data through Entropy Intelligence and the MCP server within your access rights. Never copies a row. |
| Find data by business need | Catalog Explorer for tables and schemas. | Primary place. Marketplace search, domains, and the data map, for people and agents without a Databricks account. |
| Describe data as a product with a contract, terms of use, and an SLA | Receives the descriptions and tags as comments and tags. | Primary place. Data products in ODPS, data contracts in ODCS, in Git if you like. |
| Define business concepts, relationships, and metrics | Receives the concept as a tag on the column. Pages follow once the API is available. | Primary place. Semantics in Apache Ossie, linked from the contract columns. |
| Run the quality checks of a contract | Primary place. A job runs the Data Contract CLI on your compute. | Receives the results, tracks the Data Quality Score, and notifies the owner and consumers. |
| Name the team that answers for a data product | The catalog owner stays the technical owner of the objects. | Primary place. Teams, domains, roles, and the inbox where requests and alerts arrive. |
| Request, approve, and audit access with a purpose | Enforces the grants that Entropy Data writes. | Primary place. Requests with purpose and terms, approval with an AI evaluation, audit trail, expiry, and the provisioning status. |
| Govern with policies, certifications, and classifications | Receives classifications and certifications as tags. | Primary place. Plain-language policies checked by AI, certifications, classifications inherited from concepts, and the Data Product Score. |
| Let AI agents find and use data | Primary place. Genie works on the tables and reads the comments Entropy Data wrote. | Primary place. The MCP server gives agents the business view, their own identity, and purpose-checked access. |
Getting started
- Connect your Databricks workspace based on our Databricks integration guide.
- Create your first data product from a Unity Catalog asset, write its contract, and run the checks from a Databricks job with the Data Contract CLI.
- Build the pipeline behind the contract with your coding agent, using the dbt on Databricks skill from the Skill Hub.
- Try the flow end to end in the Entropy Data demo, or start with the free Community Edition.
About the author
André Deuerling
LinkedIn of André DeuerlingProduct Engineer, Entropy Data
André is a product engineer at Entropy Data. He spends his days improving the product and working with customers to get their data products, contracts, and access flows running on their platforms.